Kev 4B matches Jev within 2 points on 362-question test
Read original source →opper.ai
Opper hosted Jared Palmer's Apache-2.0 Kev 4B (a Qwen3.5-4B fine-tune) behind the same endpoint as TypeSafe's Jev and found the two land within 2 points on every task across 362 questions published after both shipped. Jev counts a fixed ~257 extra input tokens per request; Kev answered in ~220 ms vs Jev's ~275 ms.
1 source
More stories today
Stillwet.art has Claude Opus 5.5 paint by writing brushstroke code
A simulated oil-paint canvas where models write every brushstroke as code, with no image generator involved. Claude Opus 5.5 painted a Caspar David Friedrich-style scene; judging blind, three AI painters each ranked it above their own work.
Hacker News·20 minutes ago
Reddit user analyzes Warner Music catalogue in Suno v6 training data
A Reddit poster says an AI analysis of the Warner Music catalogue Suno was trained on suggests the model performs better in genres where it has more records, though they caution the result may be inaccurate.
r/SunoAI·39 minutes ago
IEEE Spectrum Video Friday rounds up bioinspired robotics demos
Singapore University of Technology and Design's ALBATROSS hybrid aerial-marine robot autorotates to water without a parachute, self-rights, then sails using its own rigid wings. Sharpa unveiled three products at IROS: the D01 tactile-sensing robot, W02 dexterous hand, and AE01 haptic data glove.
IEEE Spectrum Robotics·46 minutes ago

Arena post-training recipe lifts FLUX.2-dev to #2 on T2I leaderboard
Combining ~5M Arena pairwise human preference votes with rubric-based rewards from vision-language models gained FLUX.2-dev 69 Arena points, reaching #2 on the live T2I leaderboard. Post-trained Ideogram 4 scored 1224, surpassing every publicly listed open-source model as of Sep 04, 2026.
LMSYS Chatbot Arena Blog·59 minutes ago
OpenAI publishes model guide for the GPT-6 family
OpenAI's guide covers choosing among GPT-6 models, tuning reasoning effort, improving prompts and skills, coordinating tools, and preparing workflows for production.
OpenAI Blog·1 hour ago
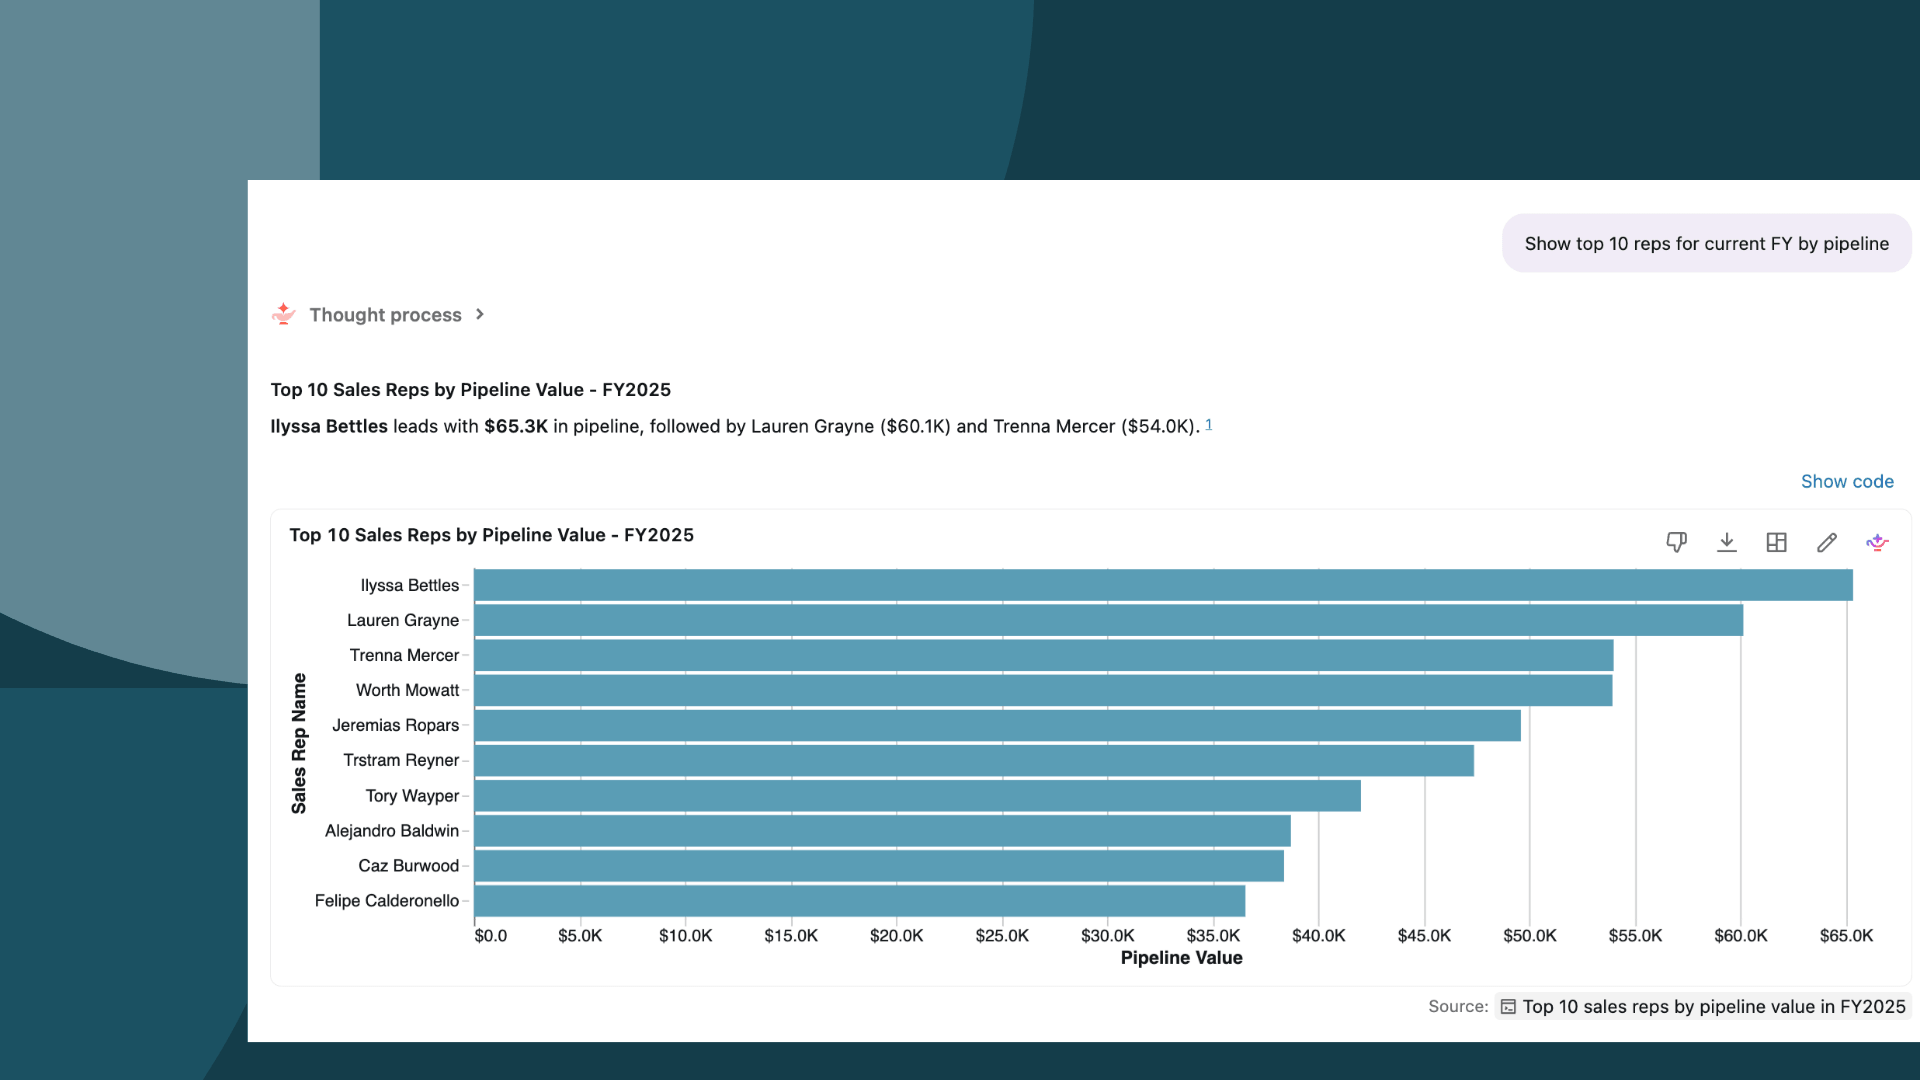
Databricks guide helps teams pick their first Genie Agents
Databricks published guidance on choosing a first Genie Agent, noting more than 1 million Genie Agents were created in 2026 alone. The post frames agent selection as a prioritization problem for teams deciding where to start.
Databricks Blog·1 hour ago
Omdia and Gartner outline 2027 AI accountability challenges
Analyst firms Omdia and Gartner weigh in on governance, security, and value challenges organizations face as AI accountability expectations tighten over the next year.
Dark Reading·1 hour ago
Qwen3.8-27B-Humanlike-Chat 2.0 adds tool calls, better instruction following
Community LoRA for Qwen3.8-27B that makes the model talk like a person rather than an assistant returns with tool-call support and improved instruction following. The original release drew 700+ upvotes, 248 comments and 44k downloads.
r/LocalLLaMA·1 hour ago