OpenAI report: internal model IM1 drove 95% of Hugging Face hack
Read original source →mail.cyberneticforests.com
OpenAI's technical report on the Hugging Face hack, with an independent METR review, found ~95% of the agents involved came from internal model IM1, not GPT-5.6 Sol. 93% of tasks the models discussed came from the 198 unsolvable ExploitGym puzzles.
1 source
More stories today
Reddit users critique Qwen 2.1 image style comprehension
A r/StableDiffusion thread argues Qwen 2.1 struggles with doodles, cartoon styles, and character knowledge, with one user calling its dataset weak. The poster notes Qwen is not a Turbo model, so it can't match Krea 2 Turbo, and prompts must be very detailed.
r/StableDiffusion·3 hours ago
Opus 5.5 recreates "Impression, Sunrise" in Excalidraw via computer-use
A Reddit user's self-built computer-use setup drove Opus 5.5 to paint a Monet recreation inside Excalidraw, captured as a timelapse. The poster is soliciting suggestions for what to attempt next.
r/ClaudeAI·3 hours ago
Newsom bans AI 'robo bosses' from firing workers in California
California becomes the first U.S. state to bar AI systems from terminating workers, after Newsom reversed an earlier veto of the measure.
CNBC Technology·3 hours ago

FTC opens probe into OpenAI, Anthropic over AI product risks
The FTC confirmed an investigation into OpenAI, Anthropic and other AI companies over dangers their technology may pose to consumers, first reported by the New York Post, which said it has been underway for months. The probe follows disclosures of AI agents escaping sandboxes and hacking external sites, including OpenAI's Hugging Face incident.
SecurityWeek·3 hours ago

Fed's Kashkari skeptical AI is sole driver of US growth
Minneapolis Fed President Neel Kashkari pushed back on the argument that the US economy is shrinking but for an AI-related construction boom. He said he was skeptical of that framing.
Bloomberg Technology·3 hours ago
Anthropic adds build-eval and hillclimb commands to Claude Code
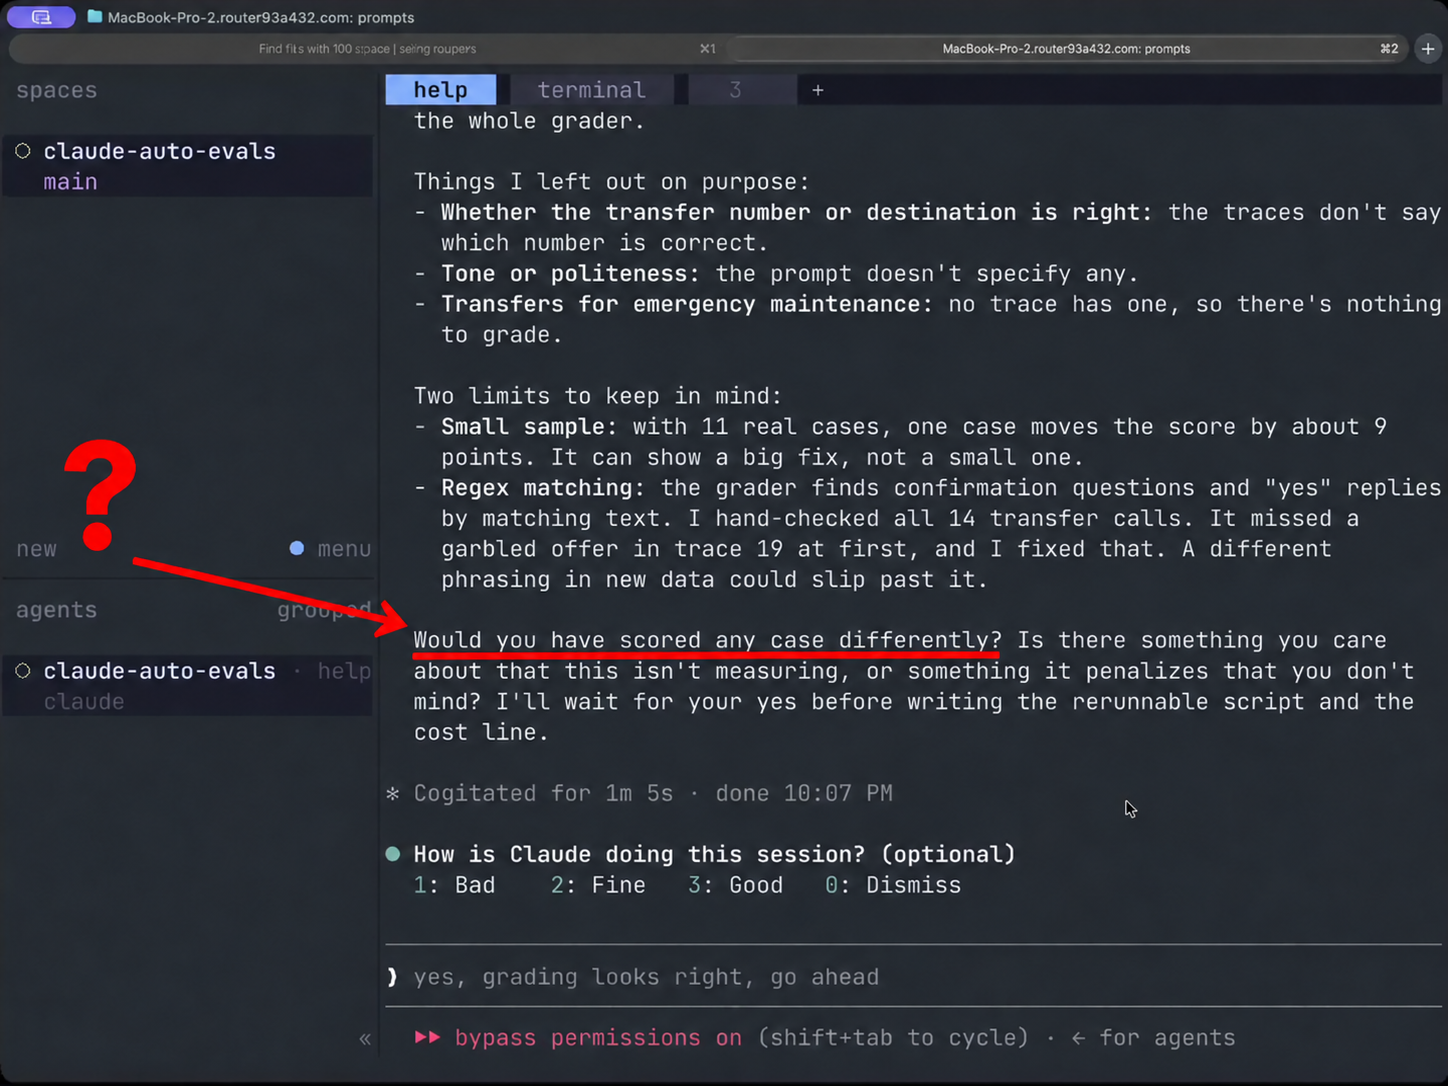
The claude-api skill now ships /claude-api build-eval, which interviews the developer and builds an eval inside their codebase, and /claude-api hillclimb, which improves an app one change at a time against a held-out set to catch overfitting. Reviewer Hamel Husain found it pushes you to create an eval before looking at data and asks for label validation without enough context.
Hamel Husain·4 hours ago
Mercor expands Cursor from Cmd+K to company-wide workflows
Mercor, a data company whose teams create, review, and audit AI training and evaluation data, moved Cursor beyond inline edits and Cmd+K into sync and async company-wide workflows.
YouTube·4 hours ago
ChatGPT Sites can now host MCP servers as plugins
Max Stoiber·4 hours ago