EmbeddingGemma 2 repurposed into on-device speech-to-text
Read original source →eg2.haku.sh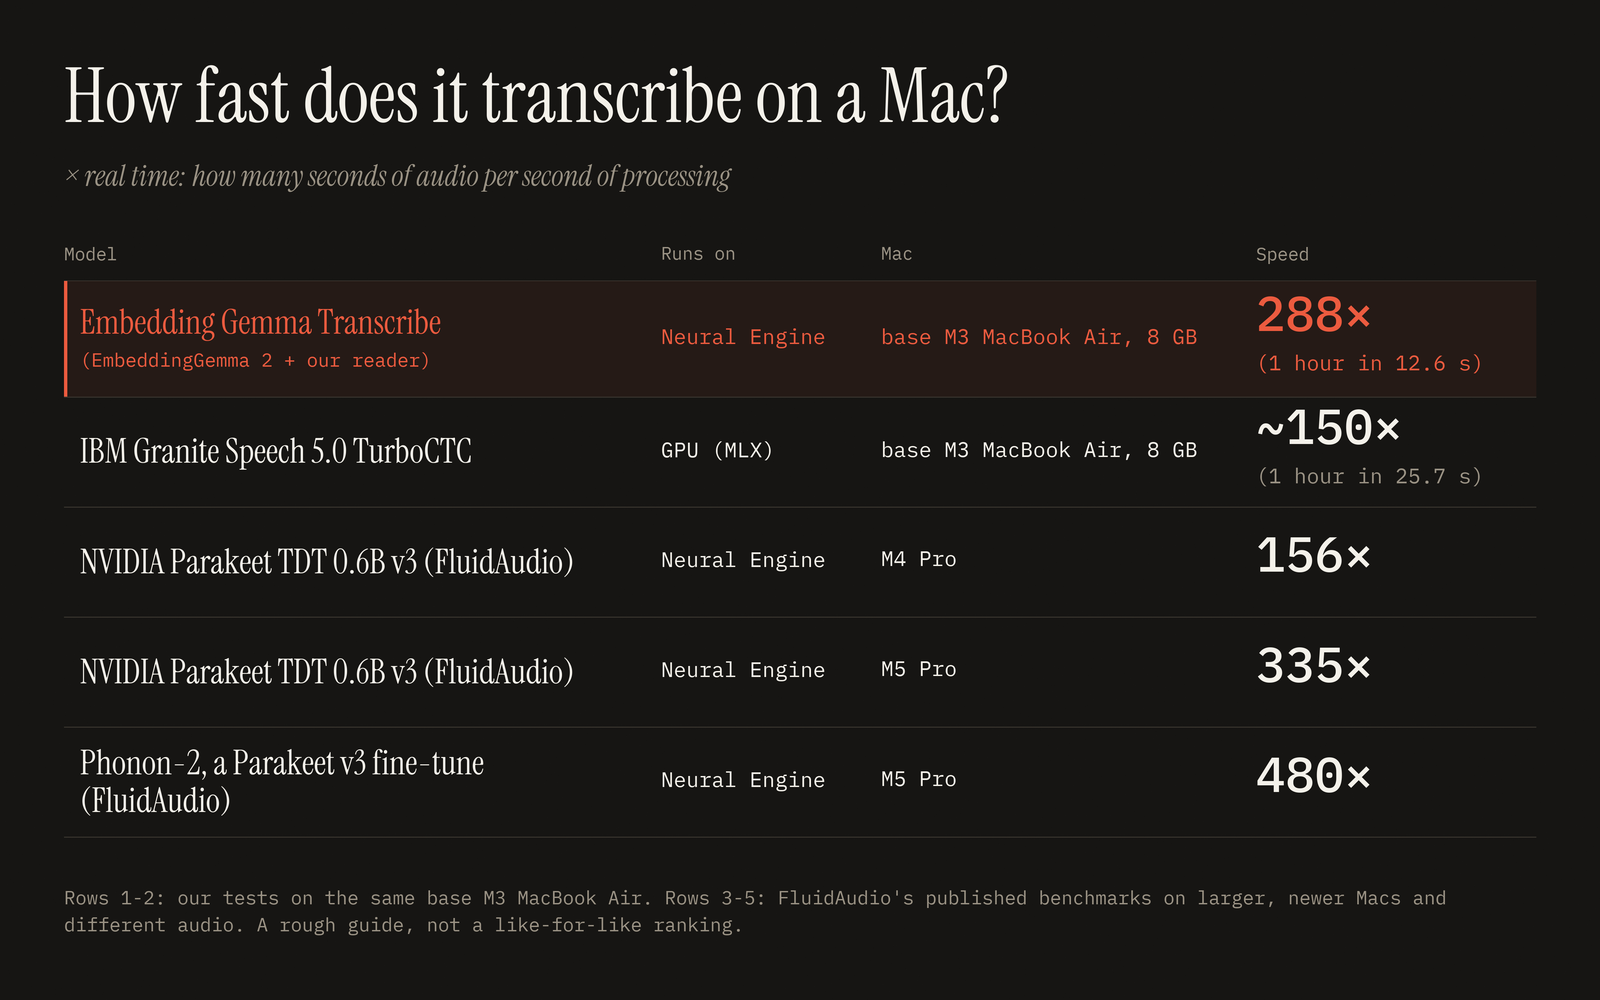
A small trained reader maps EmbeddingGemma 2's audio slices into its text space, matching against ~229,000 English words to transcribe an hour of audio in about 13 seconds on a base MacBook Air. Word error rate is ~5% versus 2-3% for leading speech models; only the reader was trained, under two hours on 8xH100.
1 source
More stories today
Scoble: AI agents merging their own PRs at hundreds of deploys a day
Robert Scoble·1 hour ago
Meta: Muse Wonder won't be open-sourced, Muse Spark weights coming soon
Meta says Muse Wonder models are too large for many people to use and carry potential safety concerns, so they will not be open-sourced. Open weights for Muse Spark are coming soon.
AI at Meta·1 hour agoAnthropic builds Scion, in-house version control, as merges hit 30k/day
Anthropic migrated its monorepo off git to an in-house version control system called Scion in five months, after daily merges grew from ~2,500 in May 2026 to over 30,000 by September. It also shipped a code review surface called Antique, code search, and a source control IAM system in the same period.
Anthropic Engineering·1 hour ago
LangChain moves MCP support into langchain.mcp for new spec
MCP support now ships in the main langchain.mcp package, built on FastMCP for the 2026-07-28 spec, replacing the separate langchain-mcp-adapters install. Elicitation is surfaced as a LangGraph interrupt and tool lists are now cacheable, matching the spec's stateless core.
LangChain Blog·1 hour ago
LangChain: open models GLM-5, MiniMax M2.7 match closed frontier models on agent tasks
LangChain's Deep Agents evals found GLM-5 (z.ai) and MiniMax M2.7 score similarly to closed frontier models on file operations, tool use, and instruction following. Outputting 10M tokens/day costs ~$250/day on Opus 4.6 versus ~$12/day on MiniMax M2.7 — about $87k annually.
LangChain uses Deep Agents CLI to make docs code samples self-testing
LangChain automated migrating inline docs code samples into standalone, CI-tested files using its Deep Agents CLI, so broken examples fail the build. The manual path otherwise requires extracting snippets, adding setup/teardown, snippet markup, and CI wiring.
Nvidia's Huang plans $2B in Europe AI deals within a week
Jensen Huang said at a Paris event that Nvidia will announce $2 billion in European investments over the next week, on a tour that also takes him to London and Berlin.
Bloomberg Technology·1 hour ago
Kai-Fu Lee: AI's opportunity is revenue, not cost savings
Kai-Fu Lee·1 hour ago