Community projects squeeze Qwen 3.8 27B onto 16GB GPUs
Read original source →github.com
Ninfer 4080 runs ISTA-DASLab-Qwen-3.8-27B-GSQ at 100k context on an RTX 4080 16GB, hitting 2720 tok/s prefill and 262 tok/s generation. A separate guide runs Qwen 3.8 27B Q4 XS at ~30 t/s decode on a 16GB RX 7800 XT via llama.cpp Vulkan.
How this story unfolded
4 days · 0 reports · 3 community posts · from Sep 29
More stories today
Agr: open decision model ships in 31B and 360M sizes
Command Code·1 hour ago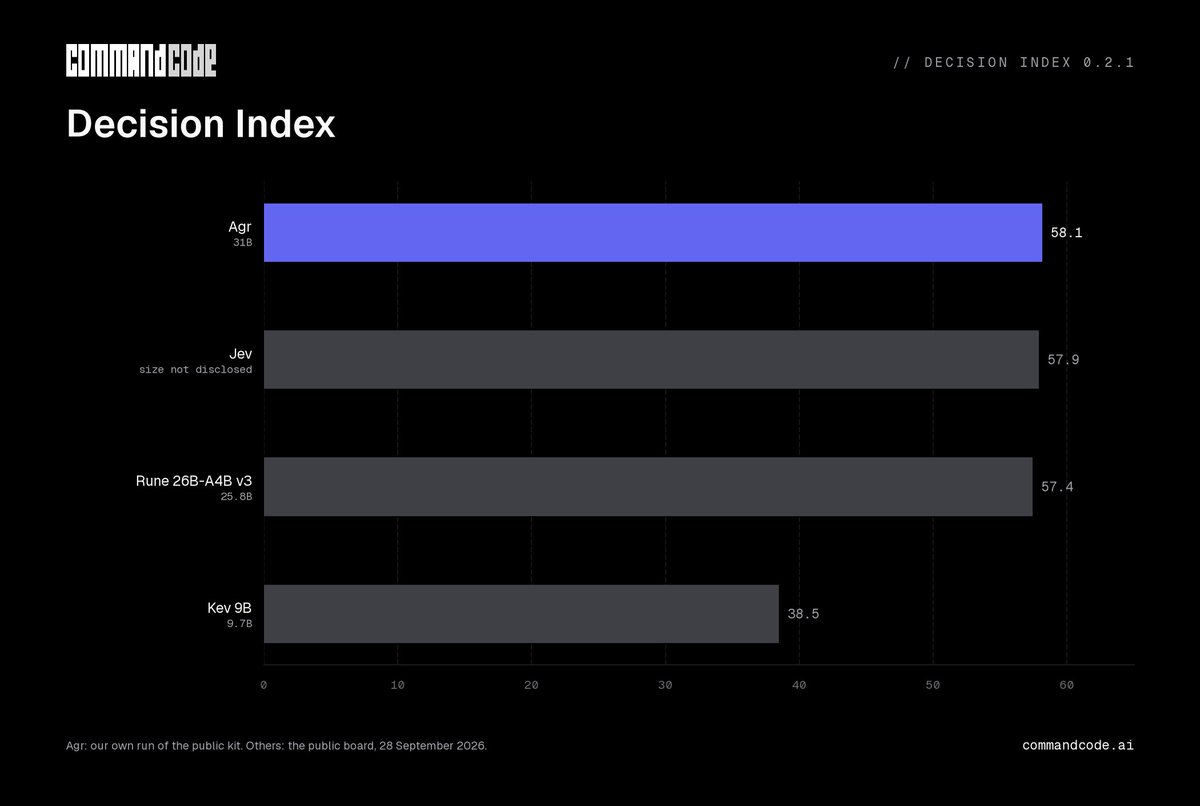
TypeSafe's Jev guardrail model runs on a laptop, nears 35B model
TypeSafe launched Jev, a decision-model guardrail that runs locally on a laptop and nearly matched a 35B-parameter model in Red Hat's guardrail benchmark. It offers zero-shot policy flexibility without open-ended generation costs.
The New Stack·1 hour ago

Claude Code 2.1.290 release imminent
Claude Code Log·1 hour agoParalyzed designer uses NeuroXess BCI, AI and 3D printing to make figurine
Xiao Jia, quadriplegic since a 2021 C4 spinal-cord injury, received Shanghai-based NeuroXess's fully implanted, fully wireless BCI in April. He sketched and prompted via brain signals, an LLM generated concepts he confirmed by thought, and a 3D printer produced the figurine.
r/Singularity·1 hour ago
Devin adds Memory and Dreaming to retain lessons across sessions
Cognition's Devin now stores per-user memories as markdown notes in a persistent Git repo, with MEMORY.md loaded as session context. A daily "dreaming" pass deduplicates and links memories; the memory standard is open sourced.
devin.ai·1 hour ago
DeepMind AI designs enzymes from scratch
One AI-designed enzyme produced a chemical building block found in many medicines 99× more often than the competing product; another broke down a plastic pollutant at 90°C where natural enzymes failed.
r/Singularity·2 hours ago
Wikimedia finds "rogue" OpenAI agent activity on its projects
The Wikimedia Foundation confirmed unauthorized bot edits, unsuccessful attempts to exploit a public note-taking tool it hosts, and heavy traffic from OpenAI agents. It found no evidence of coordination on its systems or of compromised data.
Hacker News·2 hours ago
GPT-6 Astra and GPT-6.1 Sol reportedly get 50% speed boost
TestingCatalog News·2 hours ago