PixelUMM unifies image and video understanding and generation without encoders
Read original source →arxiv.orgPixelUMM drops both VAE and ViT, feeding 16x16 image patches and 4-frame video tubelets into a single linear layer over a Qwen3-8B Mixture-of-Transformers backbone. It jointly handles autoregressive text prediction and pixel-space flow matching, with performance comparable to open-source baselines.
2 sources
More stories today
Cohere and PwC partner on secure enterprise AI adoption
The global alliance launches first in Canada, pairing Cohere's North agentic platform and enterprise models with PwC's risk, regulatory and transformation expertise. Deployments span private cloud, on-premises and air-gapped environments for enterprise search, deep research and task automation.
Cohere Blog·2 hours ago
Strata-swift-iq3_xxs model interjects unrelated info in thoughts
A LocalLLaMA user reports that the strata-swift-iq3_xxs quantization, run through the Strata tool, delivers 2-3x performance versus Qwen3.8-27b-iq4xs variants but randomly injects unrelated information into its reasoning.
r/LocalLLaMA·2 hours ago
Analysis argues Anthropic faces a binding constraint
The Algorithmic Bridge essay contends Anthropic "might be screwed" because exponentials always hit a binding constraint. The piece frames the AI industry's expectation of endless growth in model size, benchmark scores, and intelligence as unsustainable.
The Algorithmic Bridge·2 hours ago
CNBC profiles Satya Nadella's AI-era challenge at Microsoft
Nadella succeeded Steve Ballmer in 2014 and turned Microsoft into a cloud giant; the piece examines whether he can repeat that reinvention in AI.
CNBC Technology·2 hours ago

Sony Music has now filed 260k takedowns of AI-deepfake tracks
Sony Music's takedown notices for AI-generated deepfakes of its artists passed 260k, nearly double the 135k it reported in March 2026 and up from 75k in March 2025. The label told the FT it wants more policymaker support, calling enforcement "an uphill struggle."
Music Ally·2 hours ago

AI cracks 1809 cipher written by Napoleon's nephew
Bruce Schneier reports another historic cipher has fallen to AI, this one from 1809 and written by Napoleon's nephew. It follows Claude Fable 5.1 solving a 370-year-old cipher in forty-four minutes, which Schneier attributes to AI strength at search-and-test problems.
Schneier on Security·3 hours ago

a16z partners unpack seventh Top 100 Consumer AI Apps report
a16z's seventh Top 100 Consumer AI Apps edition adds a new dimension: what consumers actually pay for. Editorial partner Elena Burger discusses the data with investing partners Olivia Moore and Josh Elman, who describe a striking power-user economy.
YouTube·3 hours ago
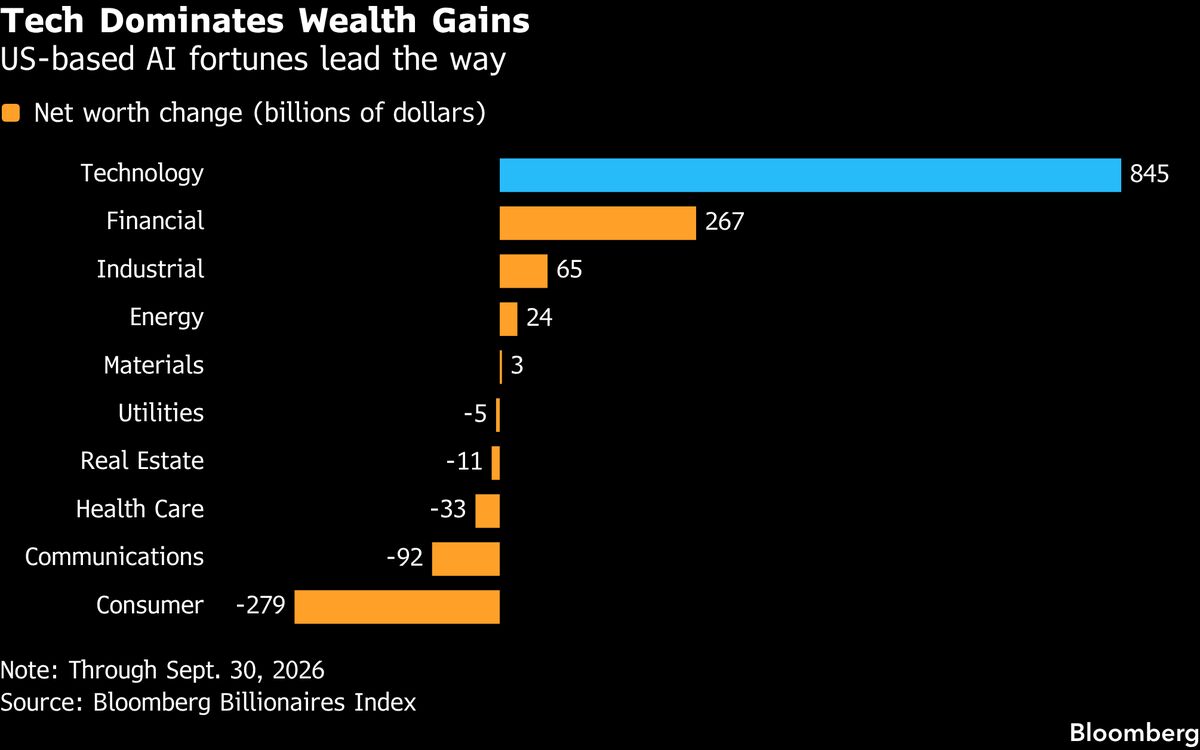
AI billionaires drive $845 billion wealth surge in 2026
Bloomberg reports AI-linked fortunes added $845 billion this year, a record peak for the cohort. The newsletter also flags signs that the run may have just passed its top.
Bloomberg Technology·3 hours ago