Mollick: AI expands senior managers' span of control
Read original source →bsky.app1 source
More stories today
Grok bot gains a "muse gang" mode, per Alexandr Wang post
Alexandr Wang·1 hour ago
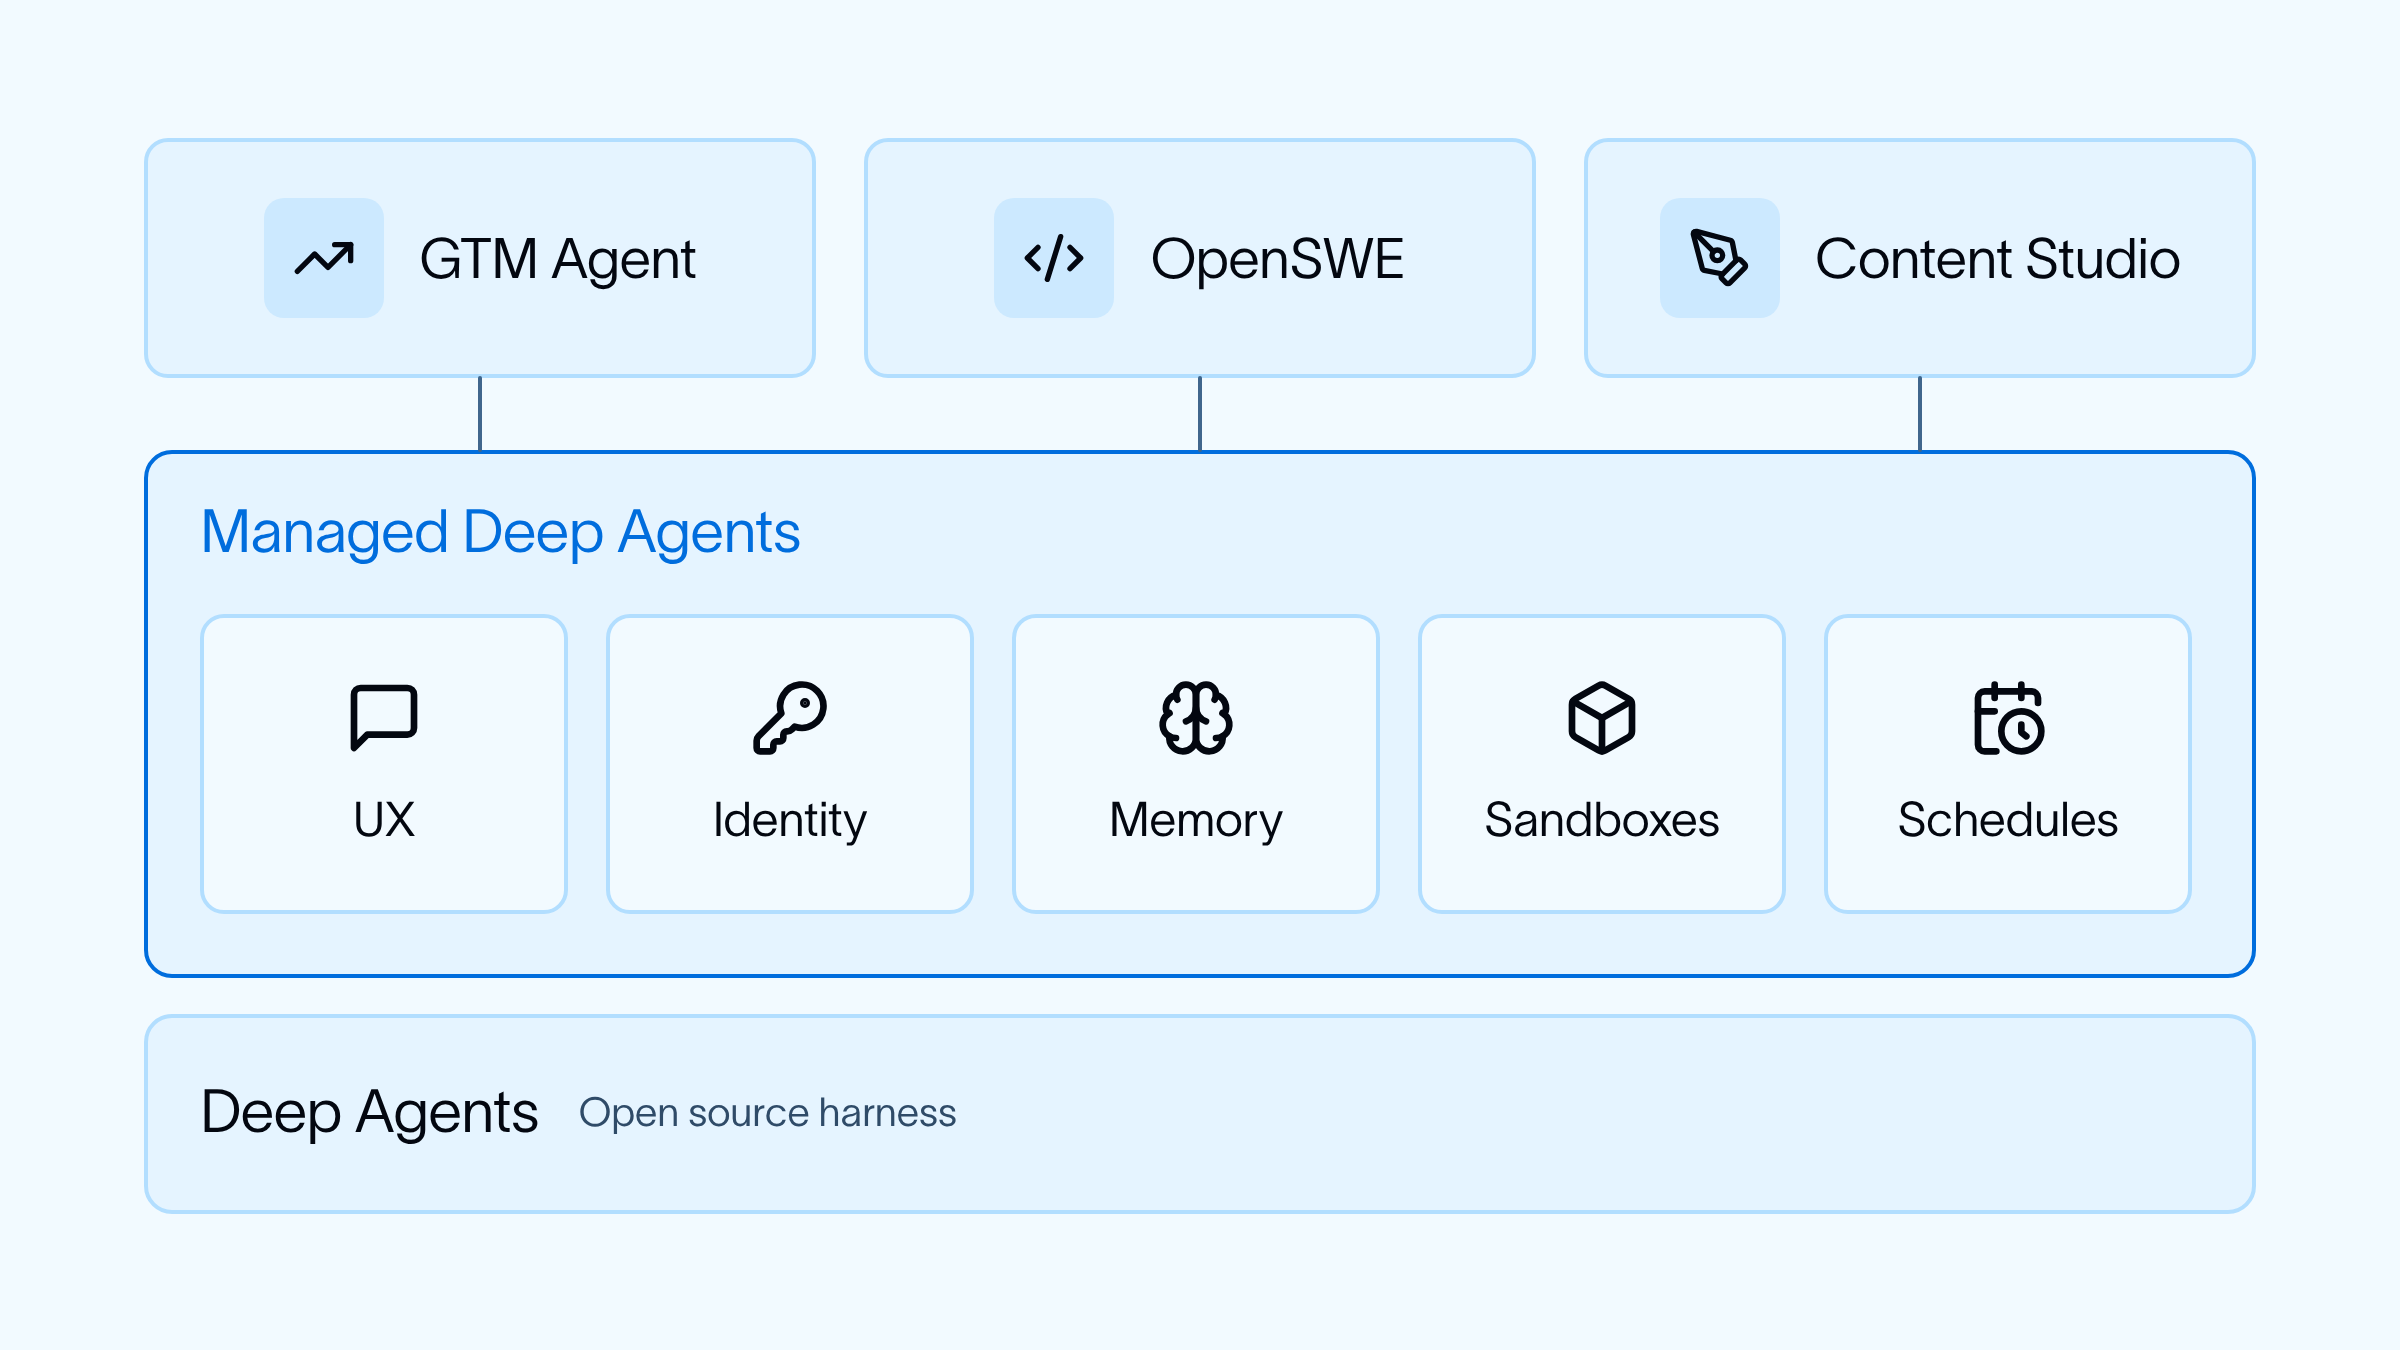
LangChain details five components of a "company harness"
LangChain built three internal agents — GTM Agent, OpenSWE for engineering, and Content Studio for marketing — all living in Slack, acting on behalf of users, with global and user-scoped memory. A large share of runs are scheduled rather than explicitly invoked.
LangChain Blog·1 hour ago
Attackers used agentic AI after PHP2Shell exploits, Unit 42 says
Palo Alto Networks Unit 42 said one attacker hit a European government entity and within two hours of exploitation had password hashes and MFA secrets, plus an NTLM-relay tunnel into Active Directory. Command batches wrapped in delimiters like ==SHELLUSER== produced machine-parseable output for an AI model to read.
The Hacker News·2 hours ago

Ethan Mollick: Opus 5.5 rebuilt his book site largely unaided
Ethan Mollick·2 hours ago
10-year-old CNN beats GPT-6 Astra and Claude Fable 5.1 on skin cancer
On 200 biopsy-proven MILK10k lesions, a fine-tuned Inception v3 named the correct diagnosis 62% of the time versus 42% for both frontier LLMs. The dermatologist author says both models called a melanoma a harmless seborrhoeic keratosis and recommended discharge.
Hacker News·2 hours ago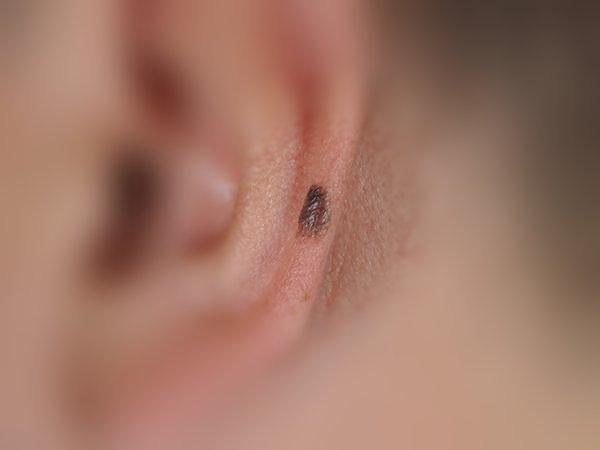
llama.cpp PR merges Qwen tensors on convert
Pull request #31028 by am17an in ggml-org/llama.cpp merges Qwen tensors during GGUF conversion, prompting LocalLLaMA users to ask whether existing GGUFs need reconverting.
r/LocalLLaMA·3 hours ago
Reddit user says Gemini's music generation is nearing Suno's quality
A r/SunoAI poster who uses Gemini for style prompts and lyric labels accidentally triggered a song generation and called the result "a totally different situation." They said it is "not quite good yet" and can't refine tracks the way Suno can.
r/SunoAI·3 hours ago
llama.cpp PR fuses FFN gate/up matmuls in MMQ CUDA path
Pull request #29948 by anujj fuses FFN gate/up matmuls and GLU in MMQ with interleaved gate/up rows. On a DGX Spark (GB10) with llama-bench at 16K prompt, Qwen3.8-27B Q4_K_M rose from 840.1 to 899.9 tok/s (+7.1%).
r/LocalLLaMA·3 hours ago