ChatGPT search now uses site: operator at scale
Read original source →simonwillison.net
Promptwatch tracking shows the share of ChatGPT Search queries containing the site: operator jumped from ~0.3-0.5% to 16-17% on August 8, aligned with the GPT-5.6 rollout. OpenAI's August 6 announcement said GPT-5.6 Sol in Chat would be "more reliable with facts and provide more focused answers."
1 source
More stories today
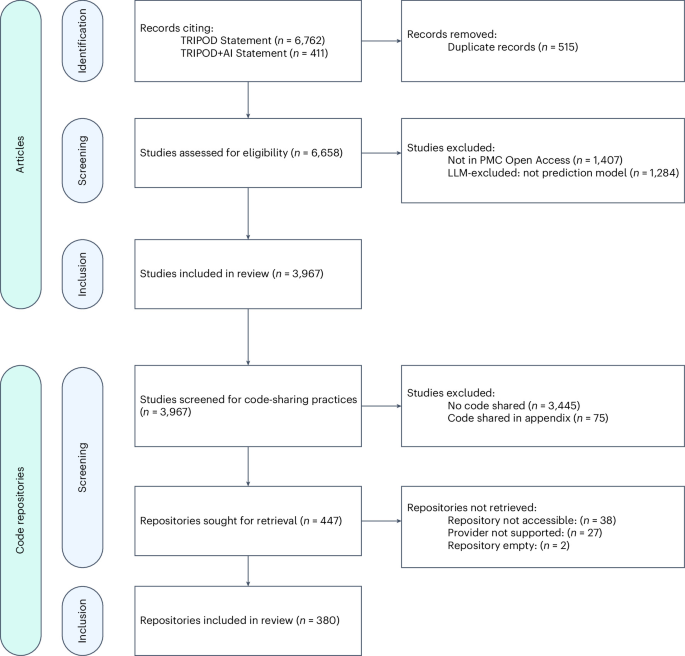
Only 12.2% of clinical prediction model papers share code
An LLM-assisted scoping review of 3,967 articles citing TRIPOD or TRIPOD+AI found just 482 (12.2%) included code-sharing statements, with prevalence varying widely by journal and country. Repositories that were shared showed substantial heterogeneity across 14 reproducibility features, informing the TRIPOD-Code reporting guideline.
Nature Medicine (News)·30 minutes ago
Meta and TikTok add agentic AI ad tools
Meta's business assistant gains campaign memory and can generate creative, adjust targeting and move budgets from chat prompts; its Ads MCP server is expanding to third-party AI tools. TikTok launched a conversational Shopping Assistant with in-app checkout.
Music Ally·31 minutes ago

OpenAI defends firing three safety researchers over breach of trust
OpenAI says Jasmine Wang, Tomek Korbak and Mikita Balesni were dismissed for violating policies on handling sensitive information, not for raising safety concerns. The trio's open letter disputes the misconduct claims and warns of a chilling effect on OpenAI's safety culture.
The Verge·38 minutes ago

Goldman: investors shifting focus to AI monetization
Goldman Sachs head of asset allocation research Christian Mueller-Glissmann says investors are questioning whether ongoing AI capital expenditure will translate into monetizable products.
Bloomberg Technology·44 minutes ago
Amazon AGI Lab's Felipe Blanes on why 80% agent reliability fails
Felipe Blanes of the Amazon AGI Lab describes lessons from taking Nova Act, Amazon's browser-agent service, from research preview to general availability on AWS. He argues benchmark scores don't hold up once real customers use the agents.
YouTube·1 hour ago
Sonar's Ali-Reza Adl-Tabatabai: AI writes more PRs, validation must be automated
Talk argues AI-generated code means more and bigger PRs and more bugs, leaving teams to either slow down or rubber-stamp reviews. Adl-Tabatabai, co-founder of Gitar (now part of Sonar), focuses on verifying code, with CI and code review as the quality gates that slow down.
YouTube·1 hour ago
Claude Haiku benchmarked at ~242 tokens/s
A Reddit post citing Artificial Analysis data reports Claude Haiku generating about 242 tokens per second, framed as notably fast output speed.
r/ClaudeAI·1 hour ago
Paper explores quantization of linear-attention models like Qwen and Kimi
Shared paper covers quantization techniques for linear-attention architectures, naming Qwen and Kimi as the models examined. No benchmark numbers or results were included in the post.
r/LocalLLaMA·1 hour ago