HarnessRL co-evolves training harness with policy for open-ended RL
Read original source →arxiv.orgHarnessRL pairs a policy with a co-evolving training harness that adapts task sampling, rollout guidance, and rubric updates to prevent reward failure in open-ended reinforcement learning. The paper targets non-discriminative and spurious rewards, using a just-in-time critic and a Rubric-Mix-10k dataset.
1 source
More stories today
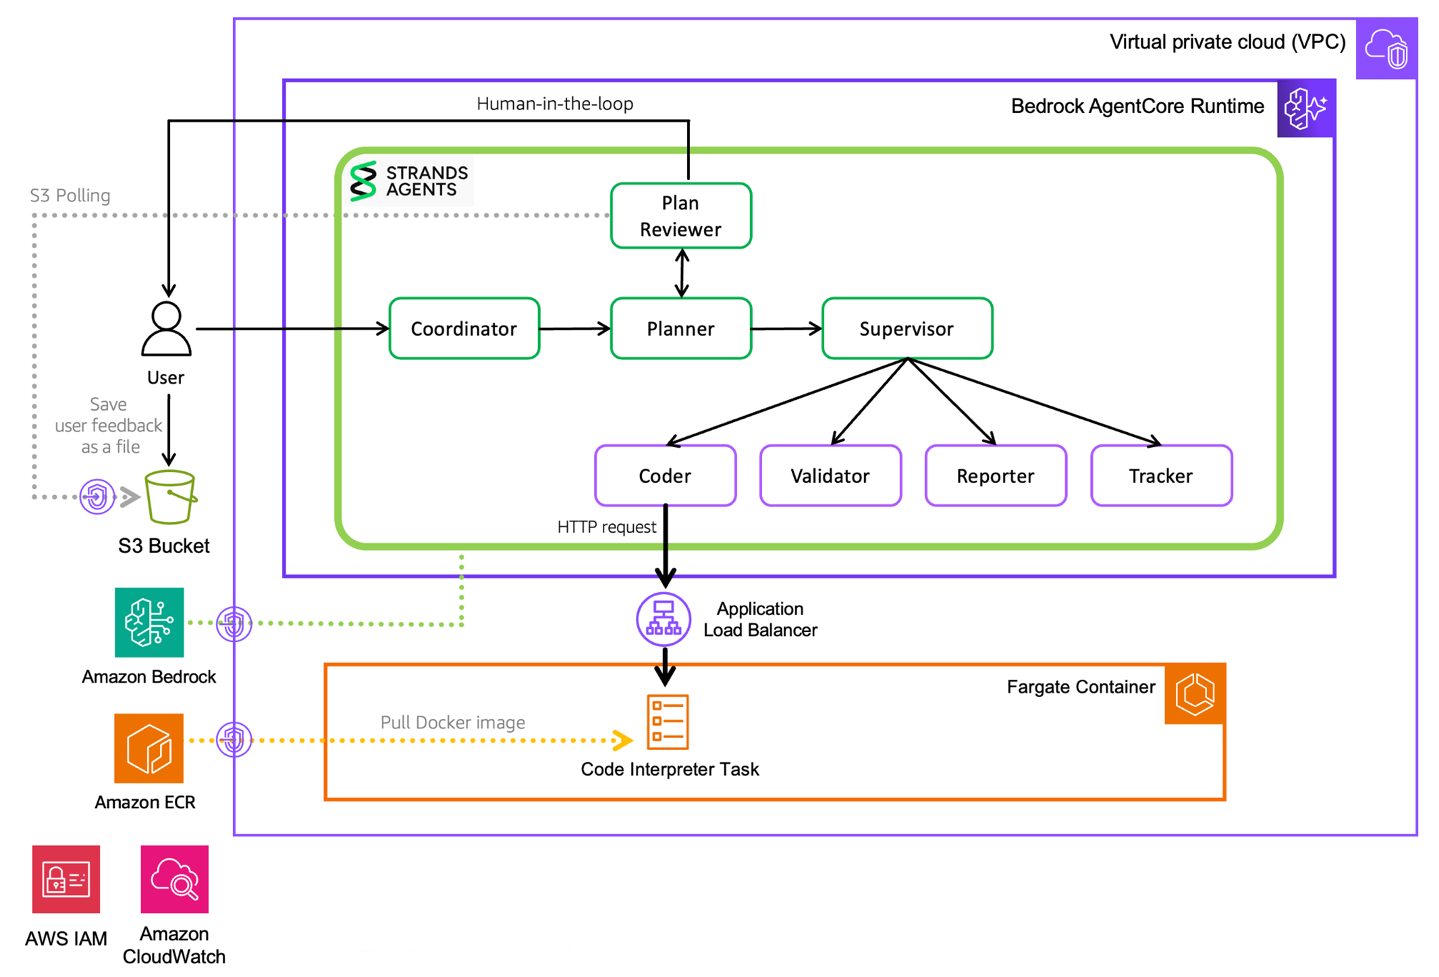
AWS blog: five production challenges in multi-agent systems
AWS's post walks through five production challenges in multi-agent systems and how Deep Insight addressed them, noting agents can be stood up in days with open source frameworks and cloud services but production is where the real challenges begin.
AWS AI Blog·1 hour ago
Qwen Code v0.26.0 adds session-targeted Skill and Extension refresh
Qwen Code shipped v0.26.0 alongside a Desktop build, adding session-targeted Skill and Extension refresh in the daemon and warm session-create for Workspace-isolated bound Sessions via the runtime broker. The release also bounds initial publication guard waits in the managed-agent path.
Qwen Code Releases·1 hour agoBlackstone's Jas Khaira says AI-buildout debt fears are overblown
Blackstone, with $1.3 trillion in assets under management, says it is the largest owner of compute outside the hyperscalers, backing neoclouds and data centers. Its BXN1 unit committed $5 billion to Crux AI, a neocloud partnered with Google to commercialize TPUs, and also backed chip startup Etched.
TechCrunch·2 hours ago

Alter (YC S25) launches access control for multi-user AI agents
Alter gives each agent its own scoped identity and keys instead of one shared over-scoped credential, with default-deny policy checks on every request. One SDK call handles storage, refresh, policy and audit for 140 providers, with LangChain, MCP and AWS integrations.
Hacker News·2 hours ago
Claude Code 2.1.307 adds API version switch and safety telemetry
The release adds /claude-api api-version to move Claude API code to version 2026-10-21, plus a claude_code.safety_event OpenTelemetry event fired whenever a permission rule, auto mode, safety check, hook or sandbox stops or prompts a tool call.
Claude Code Changelog·2 hours ago
Baseten releases Mammoth-1 and Elephant-1 decision models
Mammoth-1 (27B) ranks #1 on the Jev Decision Index; Elephant-1 (9B) is tied for #1 on the Artificial Analysis Decision Index. Both take a 16k-token context window and return choices, probabilities, and scores for classifying, routing, and scoring text.
Vercel Blog·3 hours ago
V7 cuts costs 78% while boosting accuracy with GPT-5.6 Luna
V7 Go builds a Context Graph from company files that agents query for deal screening and insurance underwriting. On V7's hardest graph-query tests across thousands of documents, GPT-6 Astra reached 89% accuracy.
YouTube·3 hours ago
Replit adds conversational automation for user guide generation
Replit·3 hours ago