Liquid AI releases Open d1 decision models for the edge
Read original source →huggingface.co
d1-3B scores 48.57 on Decision Index v0.2.1, ahead of every model under 10B and on par with Decider 35B-A3B, a model 12x its size. The 3.12B-parameter model answers in 8 ms on an RTX 4090 and 50 ms on a Jetson Orin Nano; experimental d1-omni-600M adds audio input.
How this story unfolded
2 days · 4 reports · 7 community posts · 11 of 12 shown
- Oct 7
- Oct 8
- Oct 9
More stories today
Meta's Alexandr Wang: Muse Code usage-limit bug being fixed
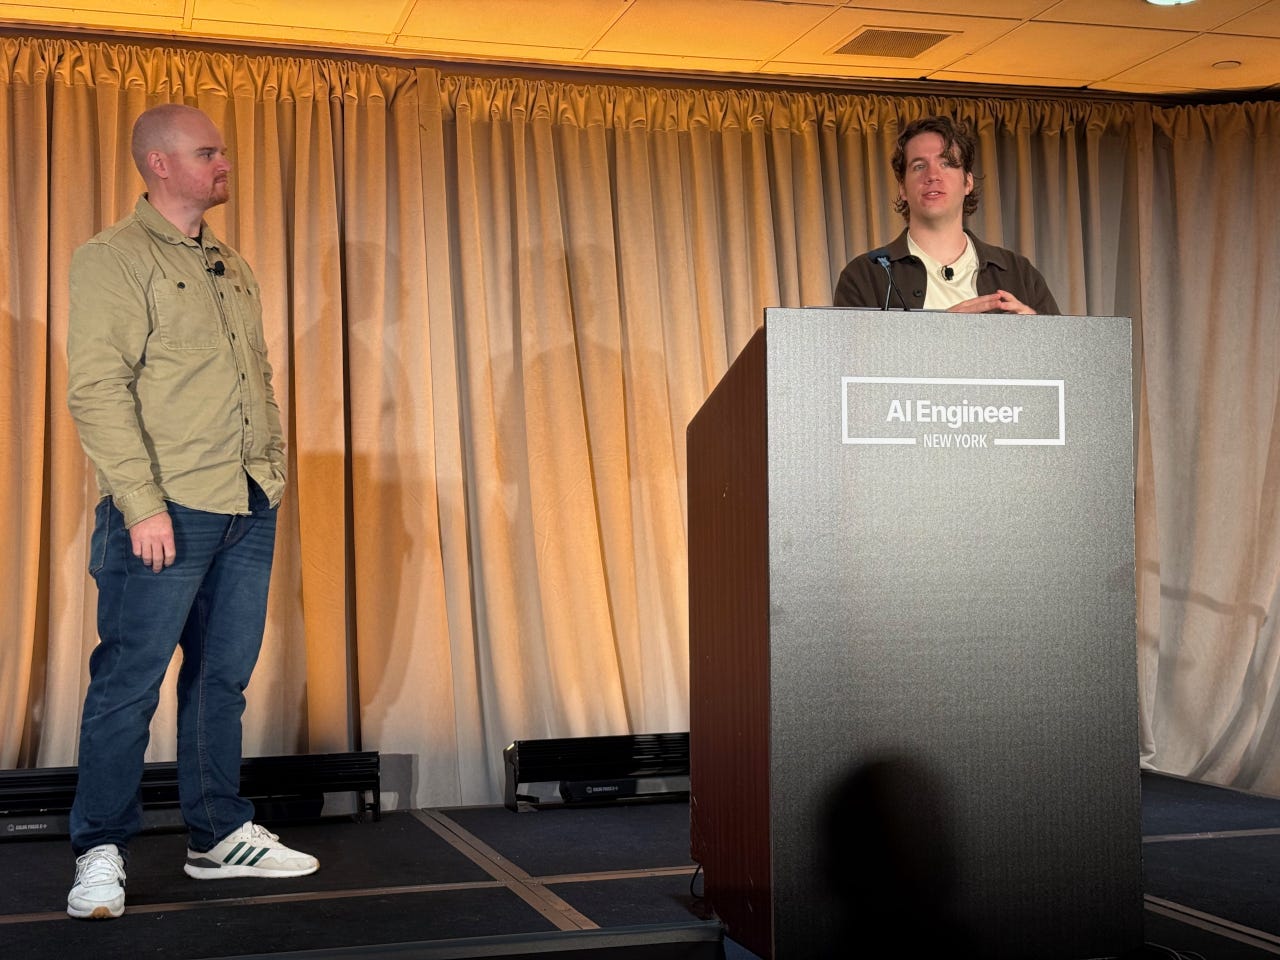
Alexandr Wang·38 minutes agoAnthropic details Claude dynamic workflows at AI Engineer NYC
Anthropic's CJ Avilla and Harrison Stall presented dynamic workflows, a new multiagent orchestration feature announced Friday, at AI Engineer New York 2026. Flows let Claude choose the organization of agents for workloads longer than a single agent or roster.
Latent Space·54 minutes ago
Essay urges developers to avoid OpenAI and Anthropic models
Security engineer Micah Lee argues open-weight models now match the latest ChatGPT and Claude on complex tasks like vulnerability research, citing private hosting via secure enclaves (Tinfoil) and provider switching as advantages.
Hacker News·55 minutes agoDeveloper builds receipt-printing mystery game on M5StickS3 with Codex
dani bauer·55 minutes ago
Perplexity Projects implements Git-based filesystem for agent collaboration
Perplexity·1 hour ago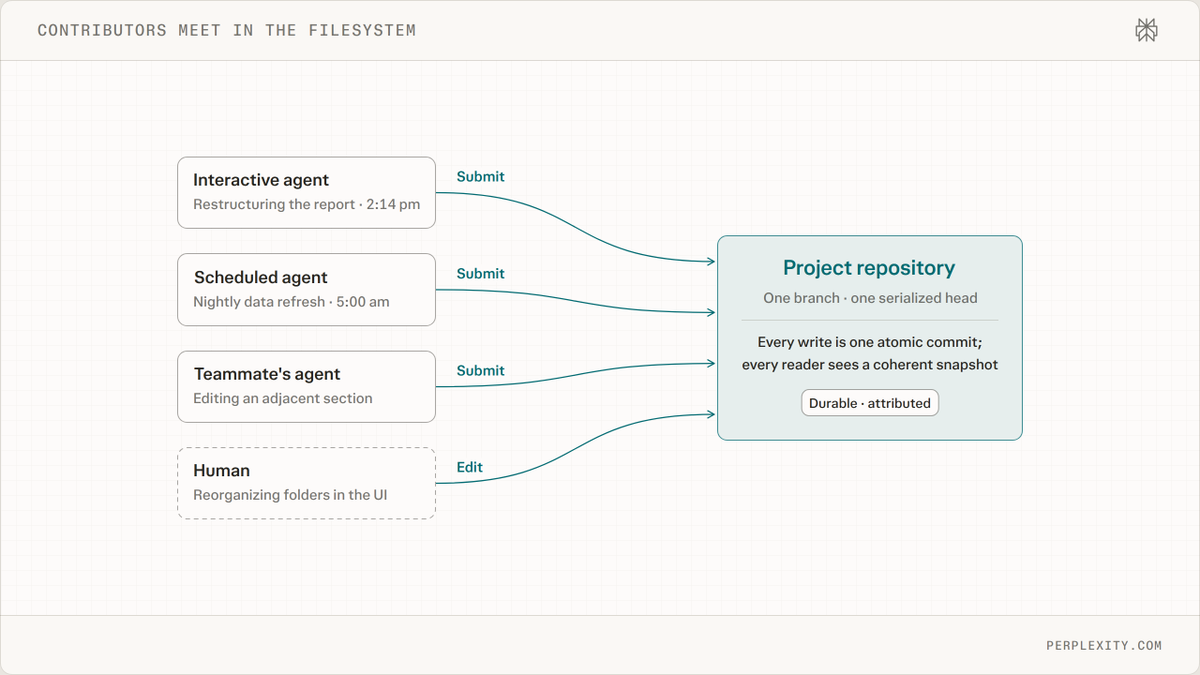
Microsoft and Musk race to reinvent the AI chip
Bloomberg's Ed Ludlow breaks down Microsoft's latest homegrown Maia chips, aimed at reducing reliance on outside semiconductors for AI. Elon Musk is testing as many as ten new chip designs a year.
Bloomberg Technology·1 hour ago
OpenAI reopens Codex Ambassador applications
OpenAI Developers·1 hour ago
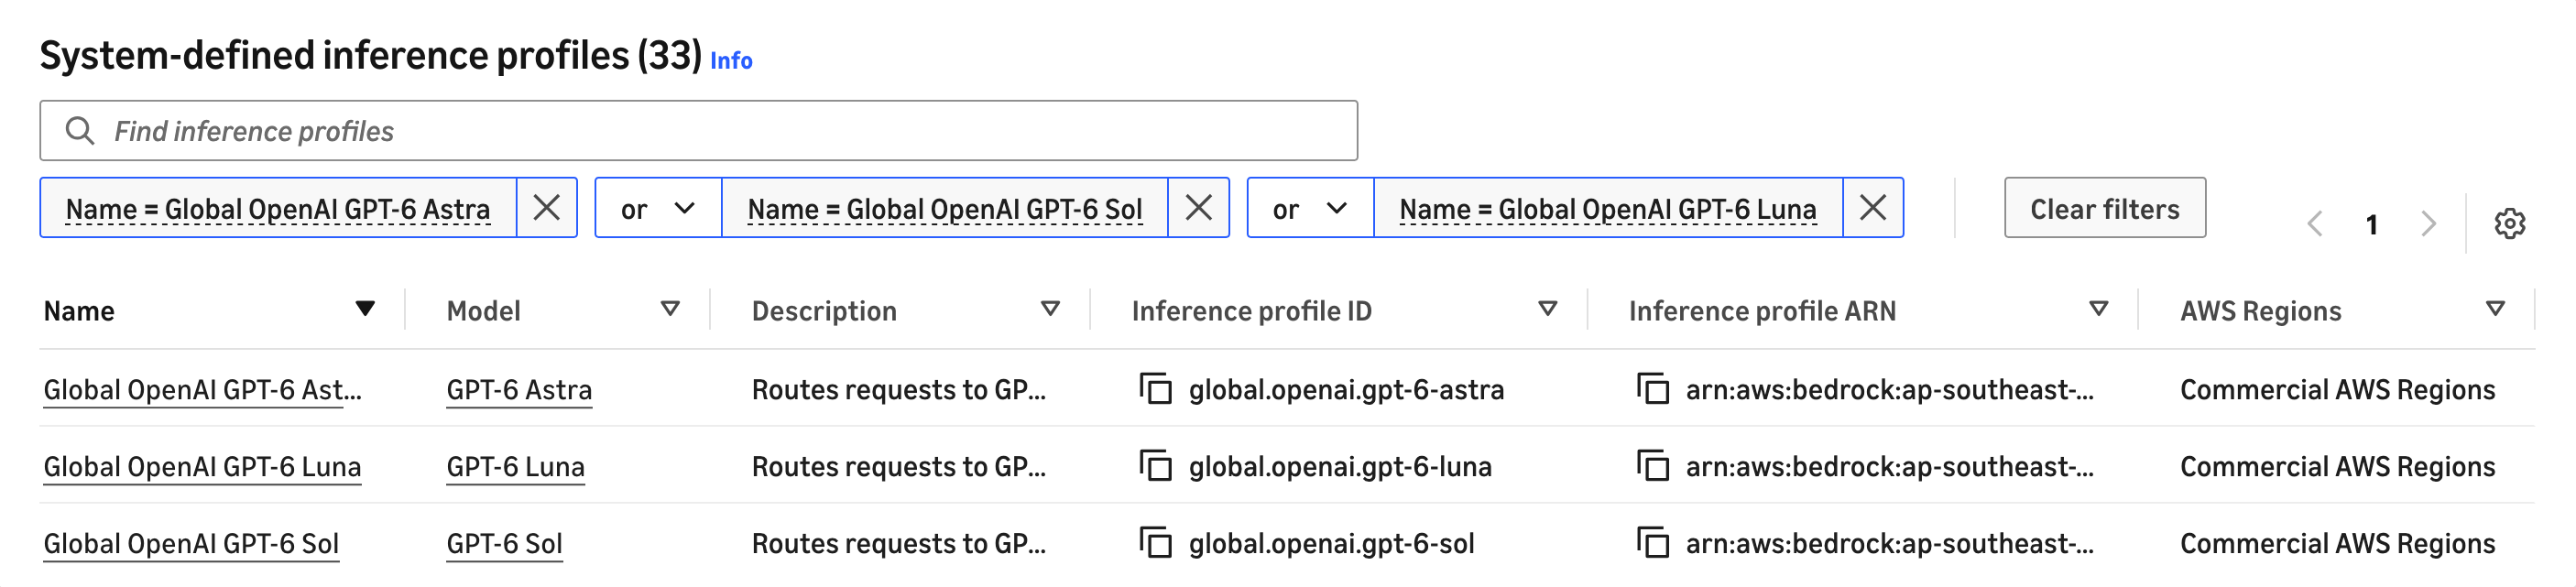
OpenAI GPT-6 Sol and Luna reach Bedrock via cross-Region inference
Amazon Bedrock now serves OpenAI's GPT-6 Sol and GPT-6 Luna through global cross-Region inference for teams in Thailand, Malaysia, Singapore, Indonesia, and Taiwan. The setup targets throttling that occurs when single-Region inference demand exceeds local capacity.
AWS AI Blog·1 hour ago