Inco Splash inference engine hits 144 tok/s on M5 Max

Open-source engine built around Qwen3.8-27B and Apple silicon claims up to 3x Ollama's decode speed, 2x oMLX, and nearly 4x when an agent fans out into sub-agents. Requires M3 or newer, macOS 26.4+, and 36 GB of memory.
1 source
More stories today
Ethan Mollick on human skills in the agentic era at Dreamforce 2026
Salesforce's Dreamforce 2026 session pairs Ethan Mollick with Paula Goldman to discuss which human skills, judgment, and instinct stay irreplaceable as AI becomes a daily collaborator.
Salesforce·3 hours ago
Nadella praises India's human capital as AI innovation driver
Speaking as guest of honour at the IDEAS 4 INDIA Indian American Tech CEOs Forum in Seattle, Microsoft CEO Satya Nadella highlighted India's growing role in global technology and AI innovation.
Mint·3 hours ago
Microsoft AI CEO Mustafa Suleyman: models must stay aligned with humanity
Suleyman, Microsoft's AI CEO, said AI models need to stay aligned with humanity's interests and called that the most responsible path for the tech industry. The CNBC Squawk Pod conversation closed a week of AI warnings from the show's guests.
CNBC Television·3 hours ago
Terence Tao previews SAIR's Open Math Model initiative
Tao's keynote at the Science x AI Summit at Caltech on September 11, 2026, co-organized by SAIR, Caltech, and the Merkin Center for Pure and Applied Mathematics, previews the Open Math Model initiative. He notes AI now generates and verifies formal proofs faster than mathematics can absorb them.
SAIR·3 hours ago
SpaceXAI releases Grok Voice Transcribe 2.0 speech-to-text model
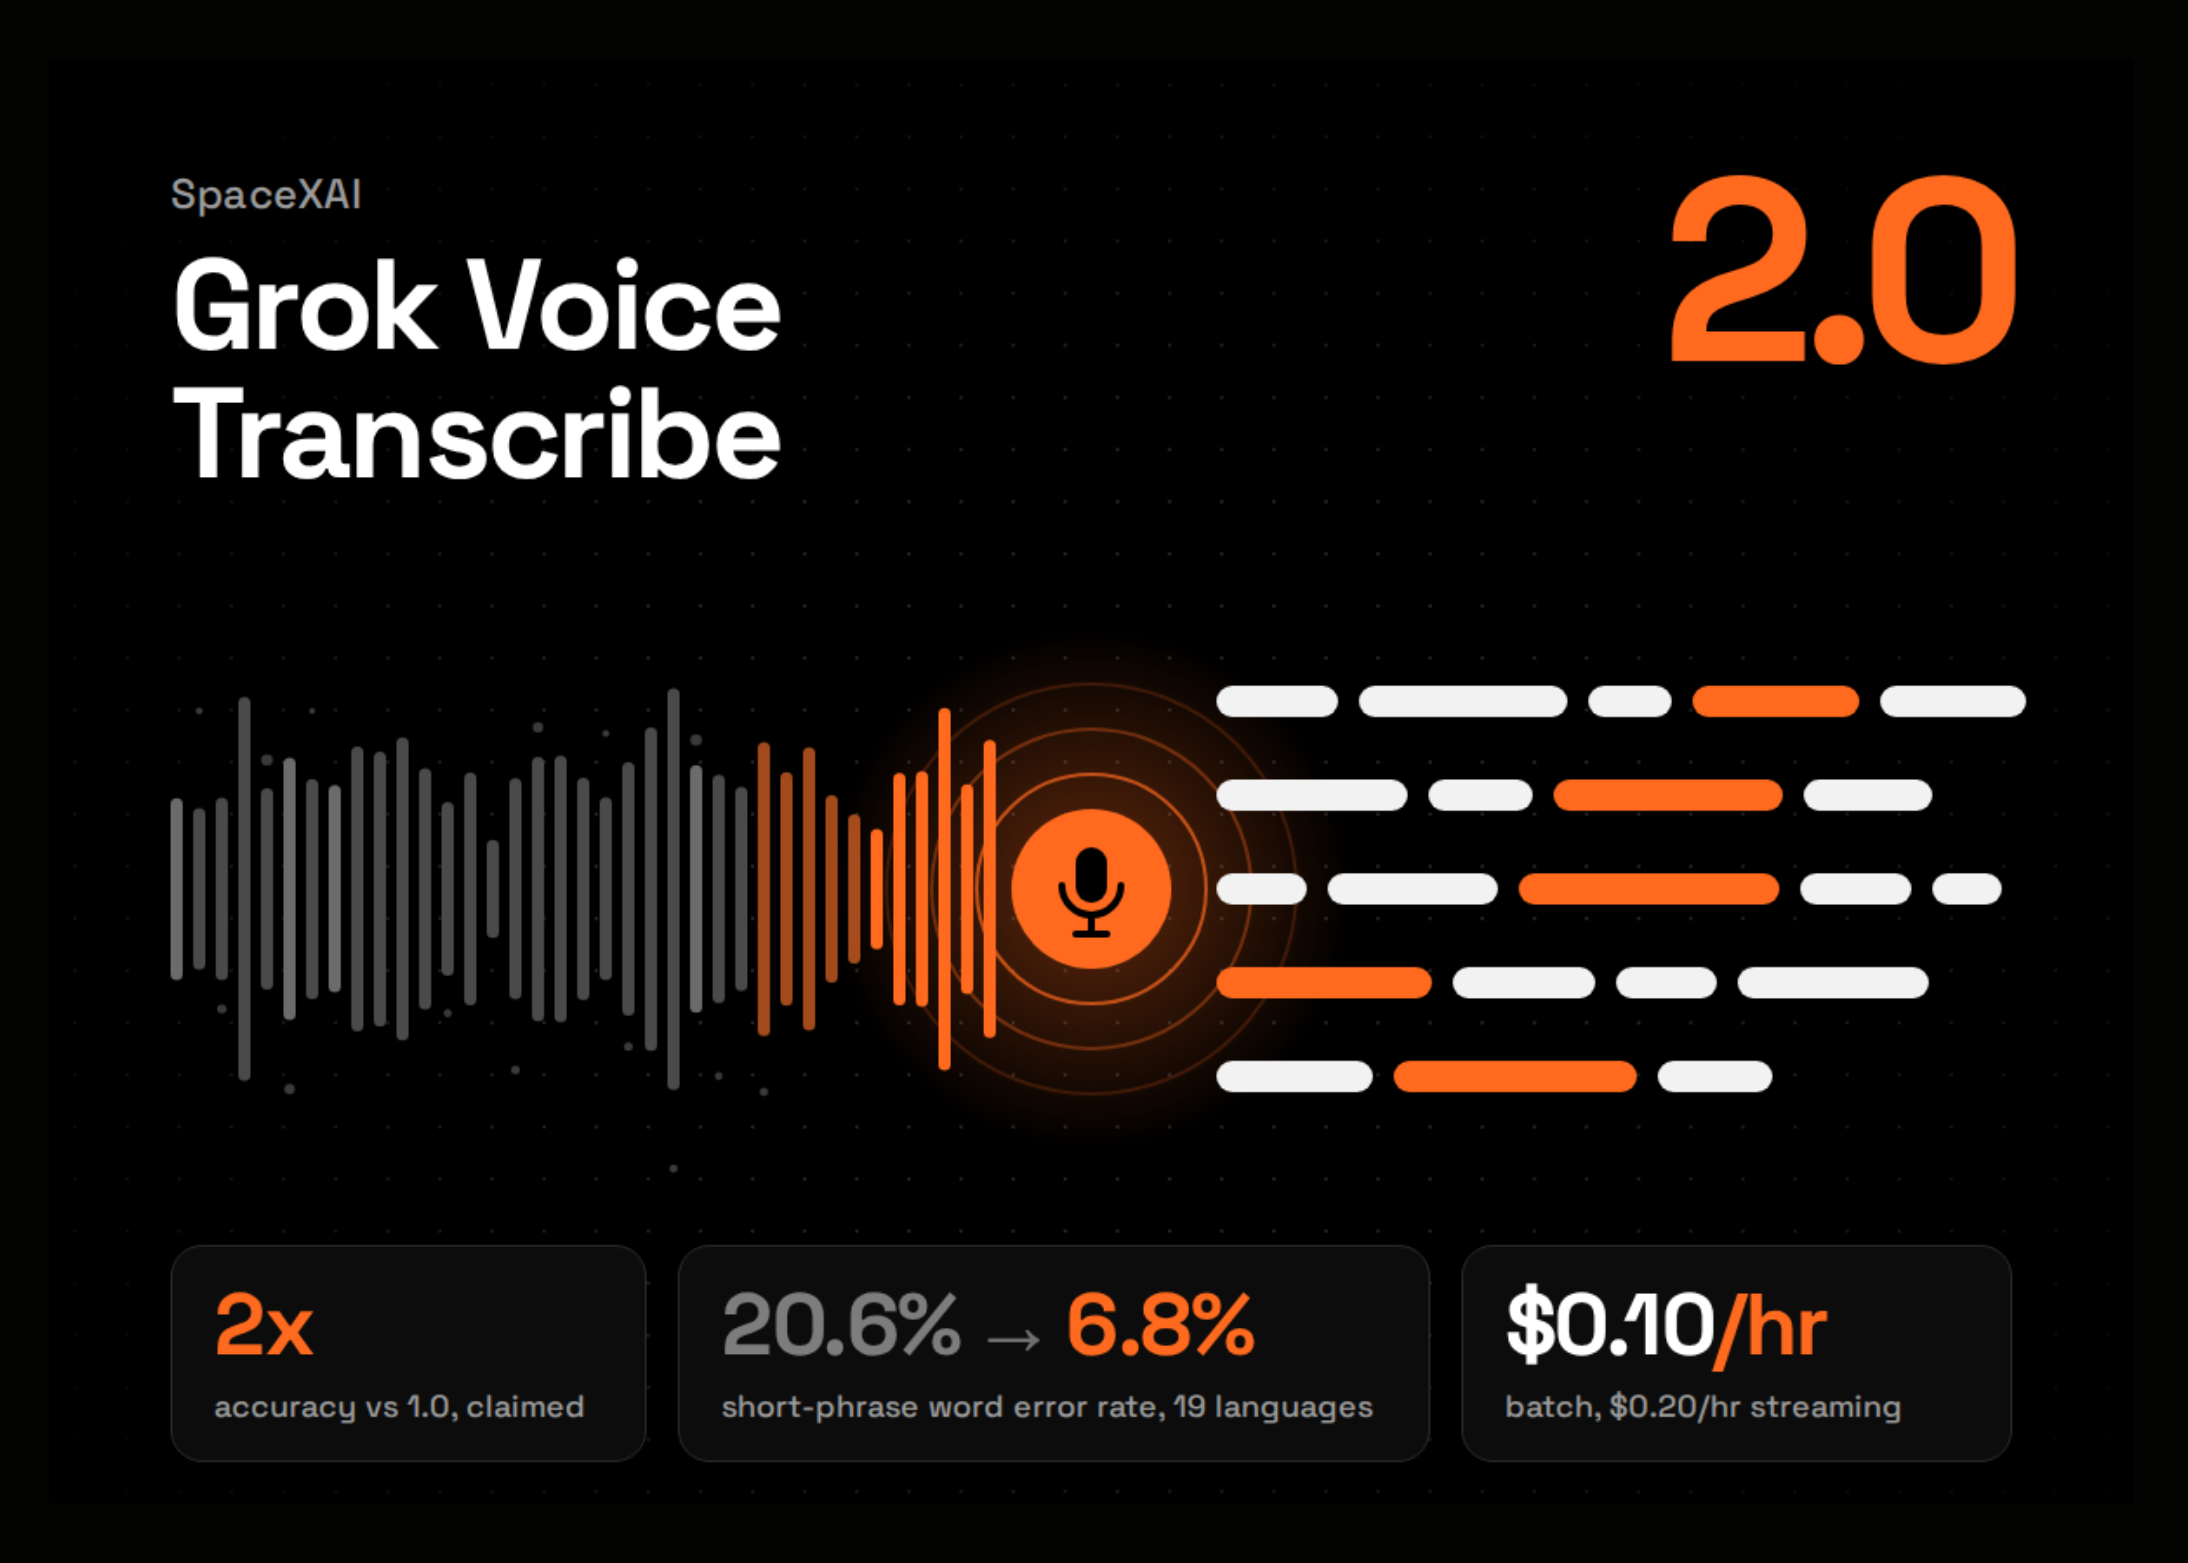
Grok Voice Transcribe 2.0 hits 2.7% WER at 0.49s after end of speech on AA-WER Streaming, ranking first among 32 streaming models. SpaceXAI claims 2x the accuracy of version 1.0 at the same $0.10 per hour price.
MarkTechPost·4 hours ago
Criticism of METR's independence as Anthropic funds Accenture audit
Timnit Gebru·4 hours agoClaude Code 2.1.278 defaults auto mode to server-side classifier
Claude Code v2.1.278 switches auto mode for Claude API and Enterprise users, plus Bedrock, Vertex, Foundry and gateways, to the server-side classifier, which does not charge for classifier overhead. CLAUDE_CODE_AUTO_MODE_SERVER=0 opts out on Bedrock, Vertex, Foundry and gateways; a new Auto mode server row in /status shows where the classifier runs.
Claude Code Releases·4 hours agoAnthropic, OpenAI, SpaceXAI, Google sued over AI 'pace' coordination
A lawsuit alleges illegal coordination between competitors over calls to 'pace' AI development, per Politico. Former FTC Chief Technologist Neil Chilson separately warns government-backed antitrust exemptions for frontier labs could create a durable 'cartel' that harms competition.
r/ChatGPT·5 hours ago