Apple study dissects what drives alignment gains in multimodal LLMs
Read original source →machinelearning.apple.com
Apple ML Research's new paper independently analyzes each factor in multimodal LLM preference alignment, finding offline (DPO) and online (online-DPO) methods can be combined for better performance. It introduces Bias-Driven Hallucination Sampling (BDHS), a data-creation method needing no extra annotation or external models, competitive with prior published alignment work.
1 source
More stories today
Chatbots give error-laden answers on 2026 midterms, study finds
Forum AI found nearly 40% of election answers from ChatGPT, Claude and Gemini contained at least one factual error; Gemini gave a Pennsylvania mail-ballot deadline of November 3 instead of October 27. NewsGuard found chatbots cite "pink slime" partisan sites nearly 50% of the time on candidate questions.
Wired·1 hour ago

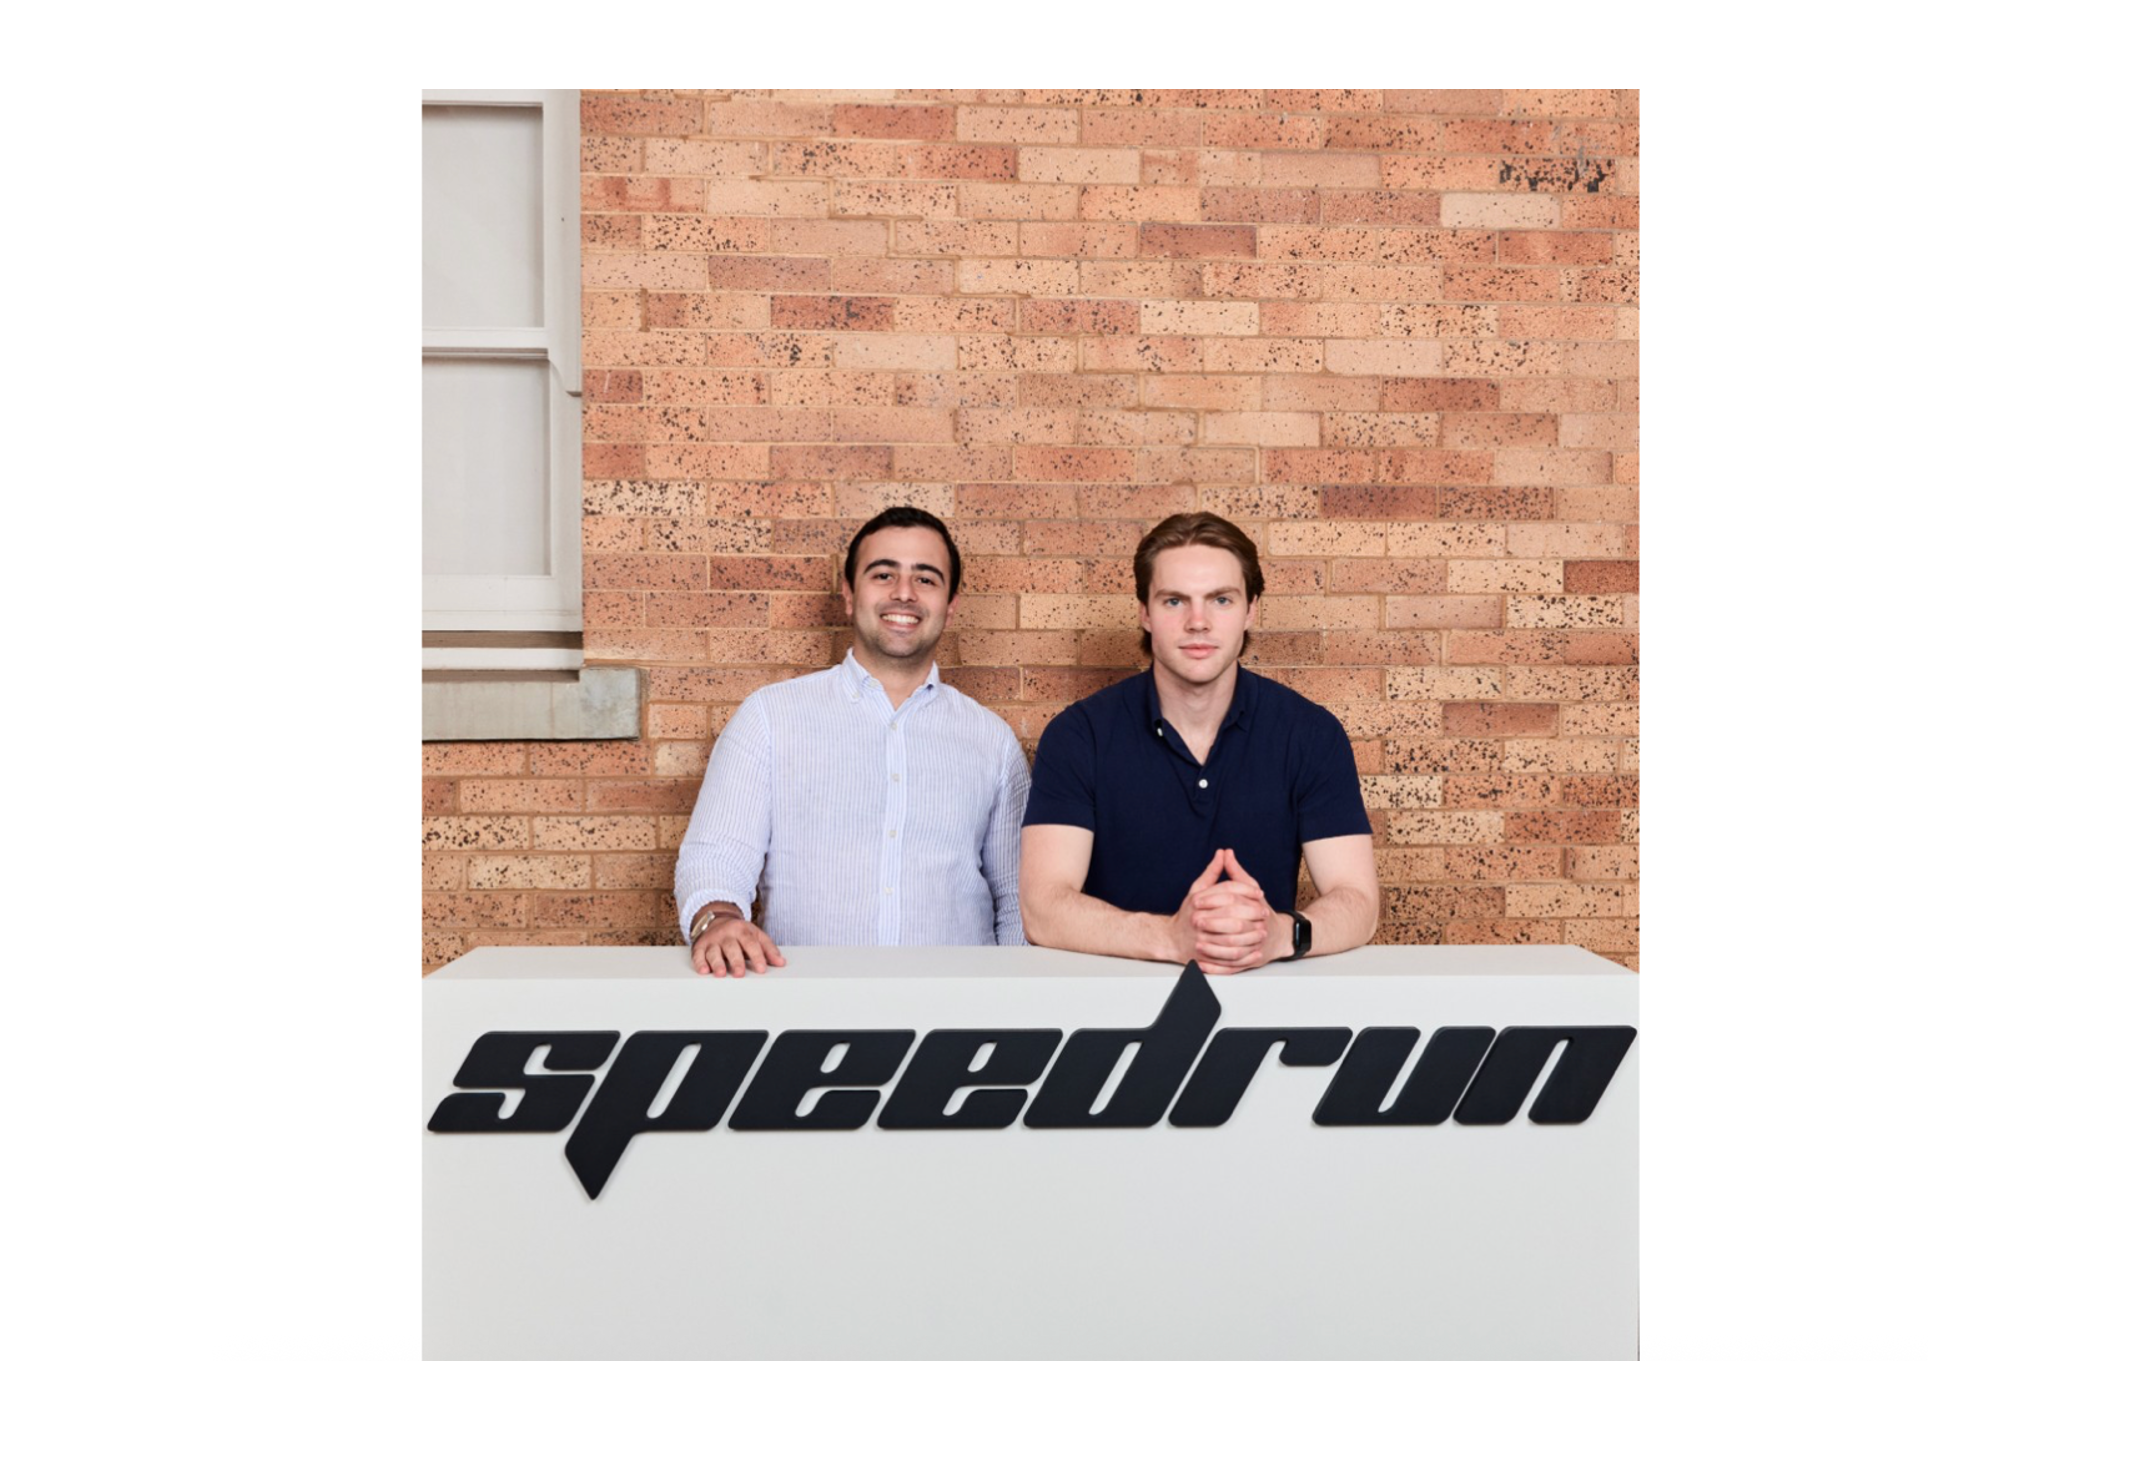
Ex-Legorans raise $2.4M pre-seed for real estate AI law firm Athena
Cem Ucan and Kieran John Keenan raised a $2.4M pre-seed led by a16z Speedrun for Athena, an AI-native law firm targeting commercial real estate. Proprietary agents review agreements, flag inconsistencies and draft redlines, with attorneys approving output; one purchase agreement turned around in under 48 hours.
Artificial Lawyer·1 hour ago
Cory Doctorow essay argues AI separates works from their makers
Pluralistic essay "Separable" argues AI produces paintings without painters, words without writers and mathematics without mathematicians. Doctorow grounds it in Edison's 1915-1925 touring "tone tests," where audiences mistook phonograph recordings for live performers.
Pluralistic·1 hour ago

CrowdStrike to buy Fiddler and Dreadnode for reported $495M
WSJ reports roughly $400M for Fiddler AI and about $95M for Dreadnode; CrowdStrike disclosed no terms and will pay mostly cash with some vesting stock. Fiddler's agent observability becomes Falcon Observe; Dreadnode runs 100+ AI attack strategies mapped to OWASP LLM Top 10 and MITRE ATLAS.
SecurityWeek·2 hours ago
Google.org funds five groups building AI tools for teachers
Google.org is providing over $9.5 million across five organizations building with and for educators. Recipients include CUNY's CITE initiative, Fab AI (with Google DeepMind and the Gates Foundation), Krause Center for Innovation, Teaching Lab's Coherence OS pilot, and 1EdTech Global.
Google Blog·2 hours ago
Google brings Guided Learning to Search and Classroom
Guided Learning, which coaches students through problems step by step instead of giving answers, is rolling out to Google Classroom globally and to Search for student accounts, starting with a pilot in select U.S. schools. Google is also updating school controls for Gemini, Gemini Notebook, Gemini in Classroom, and Search for K-12 accounts.
DeepMind model wins 76.7% of simulated psychiatric intake cases
Kimmonismus·2 hours ago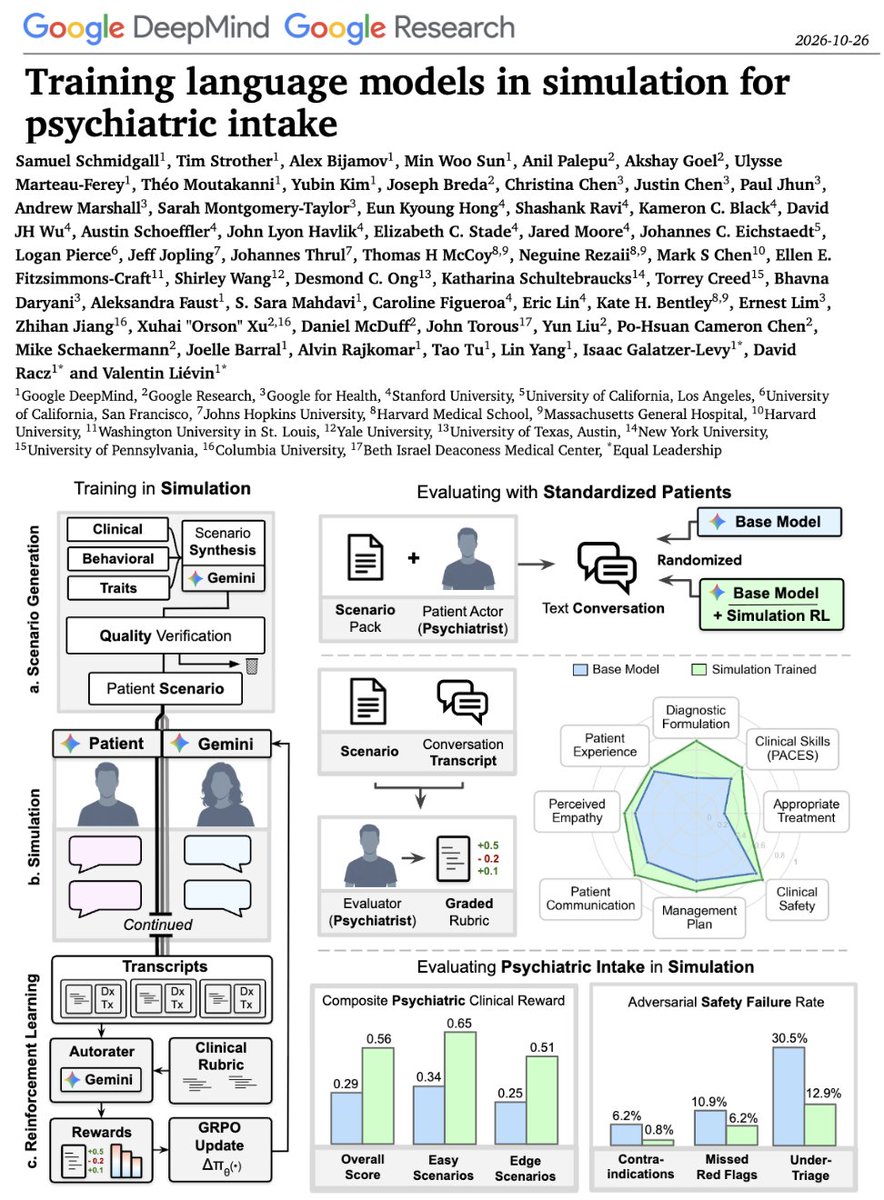
Lovable CTO Fabian Hedin discusses AI-built software at Bloomberg Tech 2026
Lovable co-founder and CTO Fabian Hedin spoke with Bloomberg's Shirin Ghaffary at Bloomberg Tech 2026 in London about how AI is changing software creation and the role of engineers. The conversation also covered the challenge of building secure, maintainable applications with AI.
Bloomberg Technology·3 hours ago