NInfer vs llama.cpp vs vLLM tested on Qwen3.8-27B NVFP4

Reddit user benchmarked NInfer, llama.cpp, and vLLM serving Qwen3.8-27B in NVFP4 on an RTX 5090, comparing output quality and speed for a production content-intelligence pipeline with long-context retrieval and structured extraction.
1 source
More stories today
Zuckerberg joins Trump in statements on accelerating AI
Reddit r/Singularity post says Mark Zuckerberg made a statement on accelerating AI, following a similar statement by Trump. The post cites a Kalshi Finance X post as its source and offers no further detail.
r/Singularity·2 hours ago
Anthropic tells investors it will be profitable for second straight quarter
Anthropic has told investors it expects a second consecutive profitable quarter, per an FT report. No figures or timeline were disclosed in the available snippet.
r/Singularity·2 hours ago
DAIR event to examine how AI is first tested on refugees
Timnit Gebru·2 hours agoReddit user tests ChatGPT image generation with max-detail prompt
A r/ChatGPT user prompted ChatGPT to ignore prior context and choose subject, style, setting, and composition itself, then render one image with maximum visual density. The post shares the resulting single render.
r/ChatGPT·4 hours ago
Tool coordinates local office of AI coding agents for terminal tasks
Tom Doerr·4 hours ago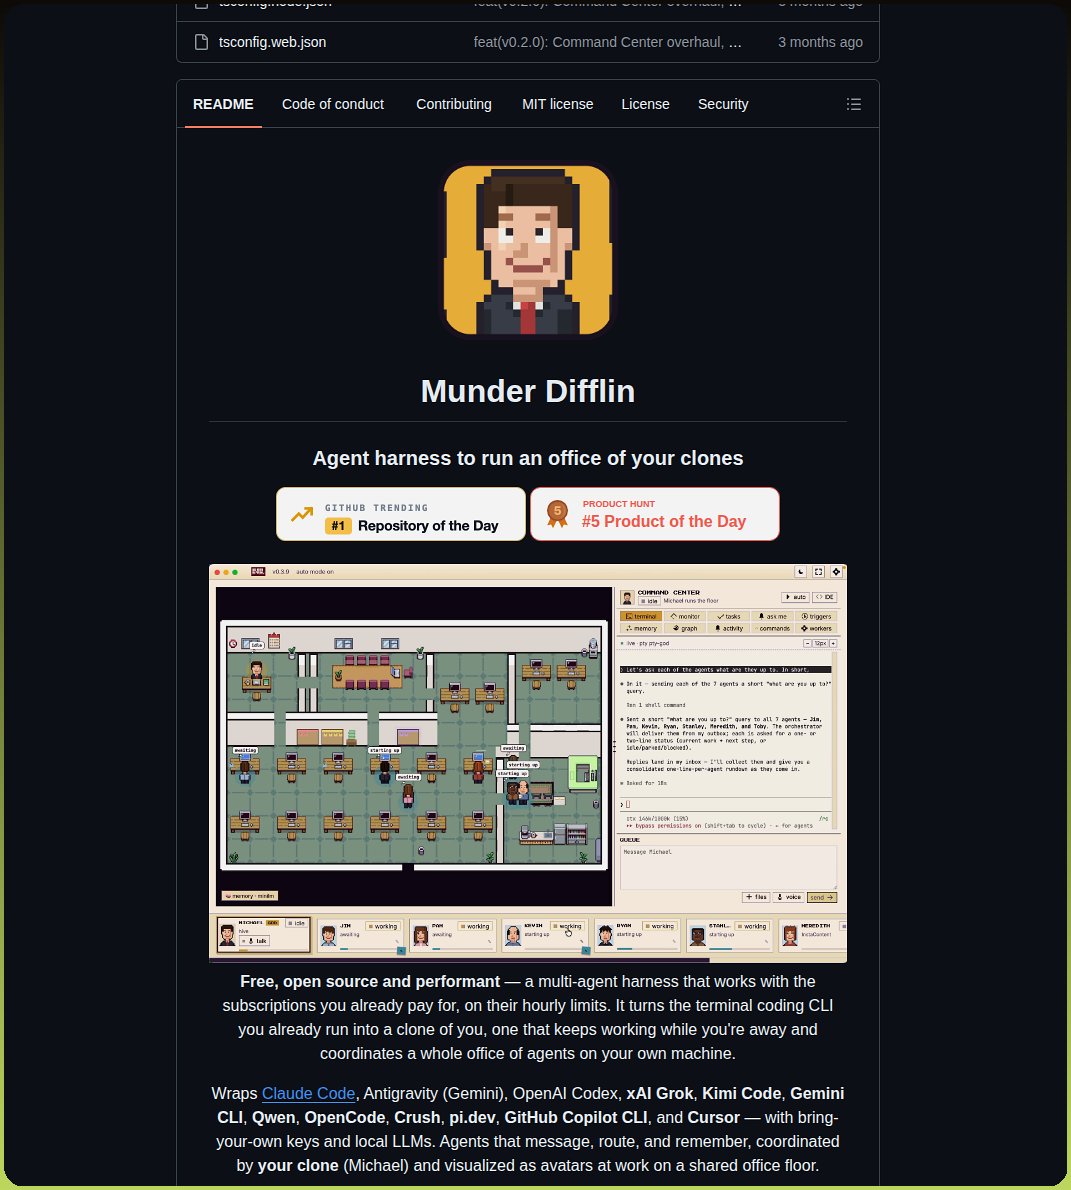
Claude Fable 5.1 solves 370-year-old Cyphral Distich cipher
Claude Fable 5.1 cracked Sir Thomas Urquhart's Cyphral Distich in 44 minutes using 176k tokens, a cryptogram unsolved since it was posed as an open problem in Notes and Queries in 1899. The key clue was the 32 Proquiritations preceding the cipher, matching its two lines of 32 numbers each.
Hacker News·4 hours ago
Reddit user reconsiders LLM skepticism after five years
A r/Singularity poster who followed AI for five years says LLMs surpassed their expectations, while still calling them an incomplete path to machine superintelligence.
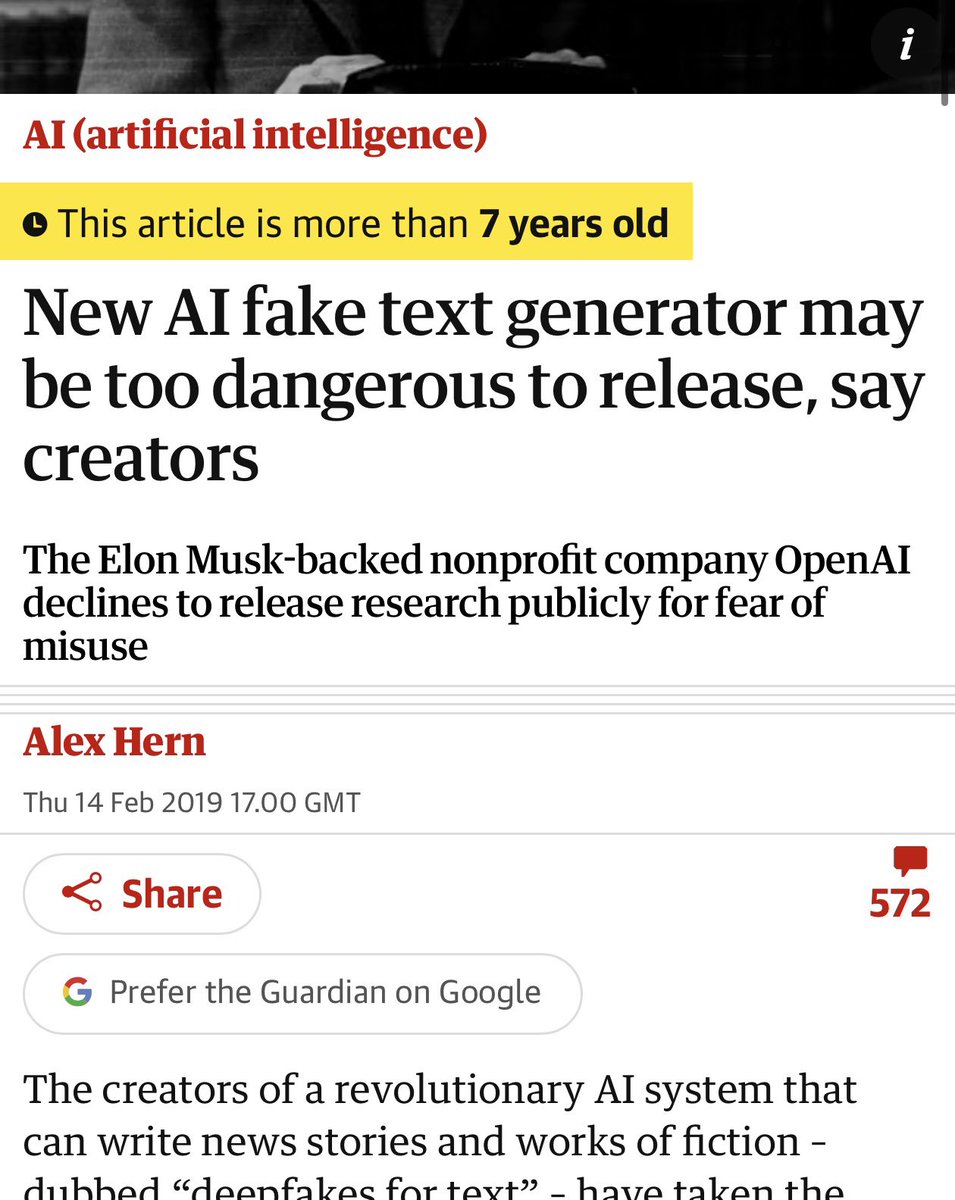
r/Singularity·4 hours ago2019 archive: GPT-2 withheld over misuse fears
Pessimists Archive·5 hours ago