LocalLLaMA users benchmark inference engines for Qwen 3.8 Flash Next
Read original source →github.com
One user reports Strata lifting Qwen 3.8 Flash Next decode from 70-80 tok/s on llamaserver to 150 tok/s. A separate test hit 504 tok/s decode on 2x RTX 5090 with QEngine 1.3.1, and a third engine, sfnx, claims ~400 tok/s on 3x V100 32GB.
How this story unfolded
11 days · 0 reports · 5 community posts · from Oct 23
- Oct 23
- Oct 27
- Oct 28
- Oct 31
- Nov 3
More stories today
Latent Space interviews Fabian Theis on AI and the Virtual Cell
Theis's Helmholtz Munich lab works on algorithms for multi-scale, multi-modal "multiomics" time-varying biological data. The episode ties into Biohub's $1.8B commitment from Biohub, NIH, DOE, Google and Meta for imaging and measurement data to train AI.
Latent Space·2 hours ago

Live training runs now streamable on Hugging Face
Hugging Face·2 hours ago
TSMC weighs making advanced AI memory chips, report says
The Information reports TSMC is considering broadening into advanced memory chip manufacturing, which would extend the world's largest chipmaker's reach across the AI hardware supply chain. No timeline, investment figure, or memory type was disclosed.
Bloomberg Technology·2 hours ago

ECB weighs review of banks' data center lending
The euro area's top banking supervisor is considering a review of data center lending to gauge risks from swings in AI sentiment and valuations. No scope or timeline for the review was disclosed.
Amazon lets users text Alexa to shop, after blocking Meta's Muse
Select US customers get a text inviting them to enable Alexa for Shopping over SMS; it rolls out to "millions more customers" in coming weeks. The agent searches listings, compares products, tracks prices, and orders on the user's behalf, and accepts photos of items.
The Verge·2 hours ago

Max Richter tells Bloomberg human composers should be paid for AI music use
Composer Max Richter told Bloomberg's Mishal Husain that human composers should get paid when AI uses their work to make music, arguing "AI systems were built on data that was stolen."
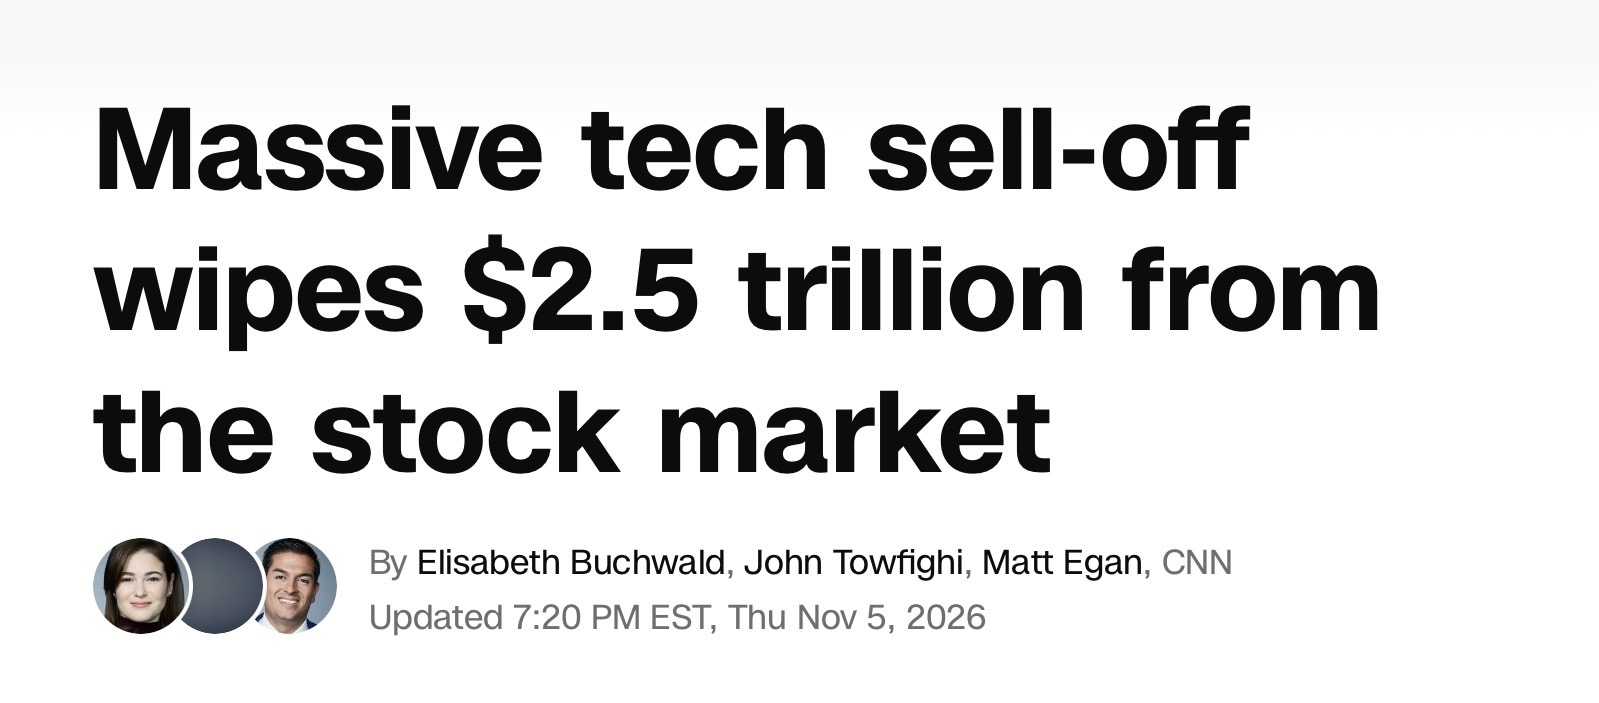
AI stocks slide $2.5 trillion, then steady as investors weigh selloff
A $2.5 trillion market drop hit AI-linked stocks, compounded by a Bank of England study finding AI still isn't delivering expected productivity gains. US stocks stabilized Friday as dip buyers stepped in, though the week's rout left investors questioning whether the worst is over.
Gary Marcus·3 hours ago
Tesla to wind down Cybertruck production for Cybercab robotaxis
Musk said Gigafactory Texas will stop building the Cybertruck around mid-2027 to make room for more Cybercab output. Tesla delivered 8,295 "other models" vehicles in Q3, down 48% year-over-year — roughly a tenth of the line's 250,000/year capacity.
Decrypt·3 hours ago