llama.cpp PR drops kq_mask from Qwen4exp QSA selection
Read original source →github.com
Pull request #30965 in ggml-org/llama.cpp rebuilds the QSA selection without the kq_mask, reportedly saving gigabytes of VRAM for Qwen Flash Next. The change is described as part of what Strata does to squeeze more from the experts' cache.
1 source
More stories today
r/MachineLearning debates whether symbolic AI is dead
A discussion thread asks why symbolic AI structures keep resurfacing in ML research despite fading after neural nets rose to dominance. The poster notes symbolic AI's 1970s heyday and argues more research should revisit it.
r/MachineLearning·1 hour agoCreator shares PS2-style LoRA generations made with FastH3-V2
Reddit user aziib generated PS2-style images with FastH3-V2 at 4 steps per 15 seconds, paired with a custom "modern ps2 style" LoRA published on Civitai.
r/StableDiffusion·1 hour ago
OpenAI shows engineer using "dots" to track bugs and fix them with Codex
OpenAI engineer Rennie Song uses a dot to collect feedback from social media and user reports, update a live tracker in ChatGPT Space, and investigate and fix bugs with Codex. OpenAI is pitching the workflow as "using dots to build better dots."
YouTube·1 hour ago
Grok Bot adds Vault for logins, contacts and card info
TestingCatalog News·1 hour ago
Microduck robot preorders top 20,000 after Jensen Huang's GTC Berlin demo
Hugging Face's Clem Delangue said preorders passed 20,000 units after Nvidia's CEO showed the $399 robots at GTC Berlin; Thomas Wolf counted over 4,000 sold in 24 hours versus ~3,000 on launch day. Deliveries are slated before Christmas.
TechCrunch·1 hour ago

Coding agent harness can triple cost without accuracy gain, study finds
A study finds an agent's harness configuration can triple its cost without improving accuracy. The scaffolding around the model, not just the model itself, drives spend.
VentureBeat·1 hour ago
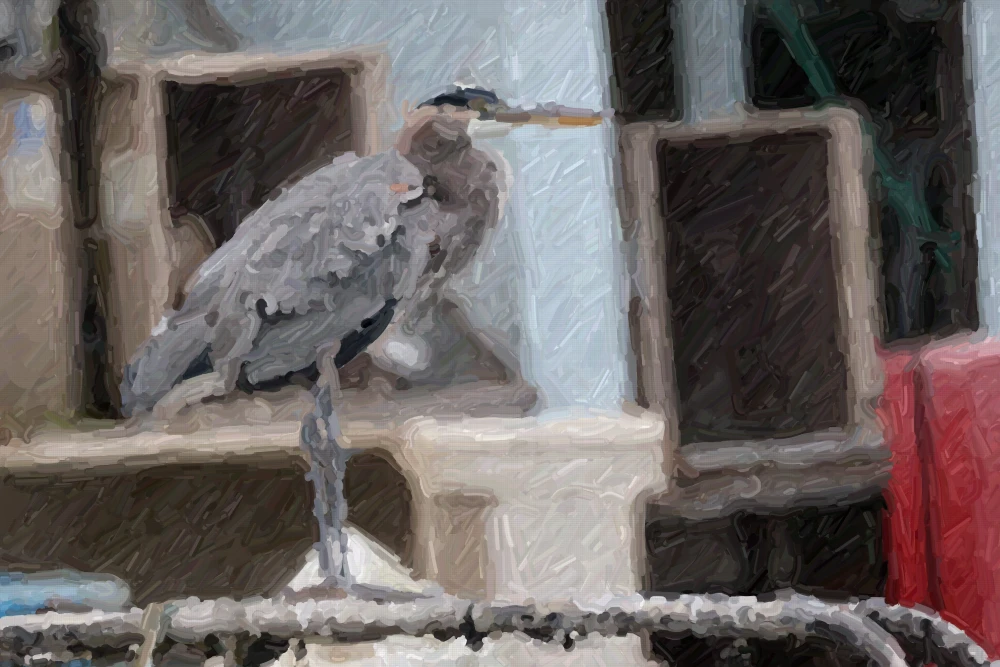
Simon Willison's Quick Study paints photos with simulated brushstrokes
Built from a prompt to Claude Opus 5.5 High, the artifact repaints an uploaded photo in a few seconds using a canvas element and simulated paintbrush. It relies on Sobel edge detection with no external libraries beyond Google Fonts.
Simon Willison's Weblog·1 hour ago
AlixPartners co-CEO Rob Hornby on the AI bull case
Hornby says AI costs are falling faster than comparable technologies historically but remain substantial, with companies in a transition period where investment is underway and returns uneven. The shift from flat fees to per-token charges has exposed costs.
Bloomberg Technology·1 hour ago