NVIDIA ReplaySSM speeds hybrid-model decoding
Read original source →developer.nvidia.com
ReplaySSM stores SSM state as a checkpoint plus a buffer of recent inputs, separating output computation from state updates. NVIDIA says SSM layers can bottleneck latency up to 100K tokens of context at serving batch sizes. It is integrated into TensorRT-LLM, vLLM, and FlashInfer, and runs in production in GLM-5.3-Flash and Kimi-K3.
1 source
More stories today
Yann LeCun to discuss JEPA world models at Tokyo industrial AI event
Christopher Nguyen ⽗·1 hour agoOpenAI adds new roles at Dublin EU headquarters
OpenAI announced new jobs in Dublin, expanding its European headquarters. The ChatGPT-maker's Irish office is its EU base.
Bloomberg Technology·1 hour ago
EXL3-QLoRA enables QLoRA training on ExLlamaV3 quants at 2-8bpw
A fork of ExLlamaV3 adds native training in plain PyTorch without transformers, letting users fine-tune quantized models across 2-8 bits per weight. The author says it has been in development for several months and is now stable enough to share.
r/LocalLLaMA·1 hour ago
Subquadratic's SubQ Snap processes 100K tokens in under a second
Kimmonismus·1 hour ago
New paper claims SOTA harness for automated theorem proving
Julia Kempe·1 hour ago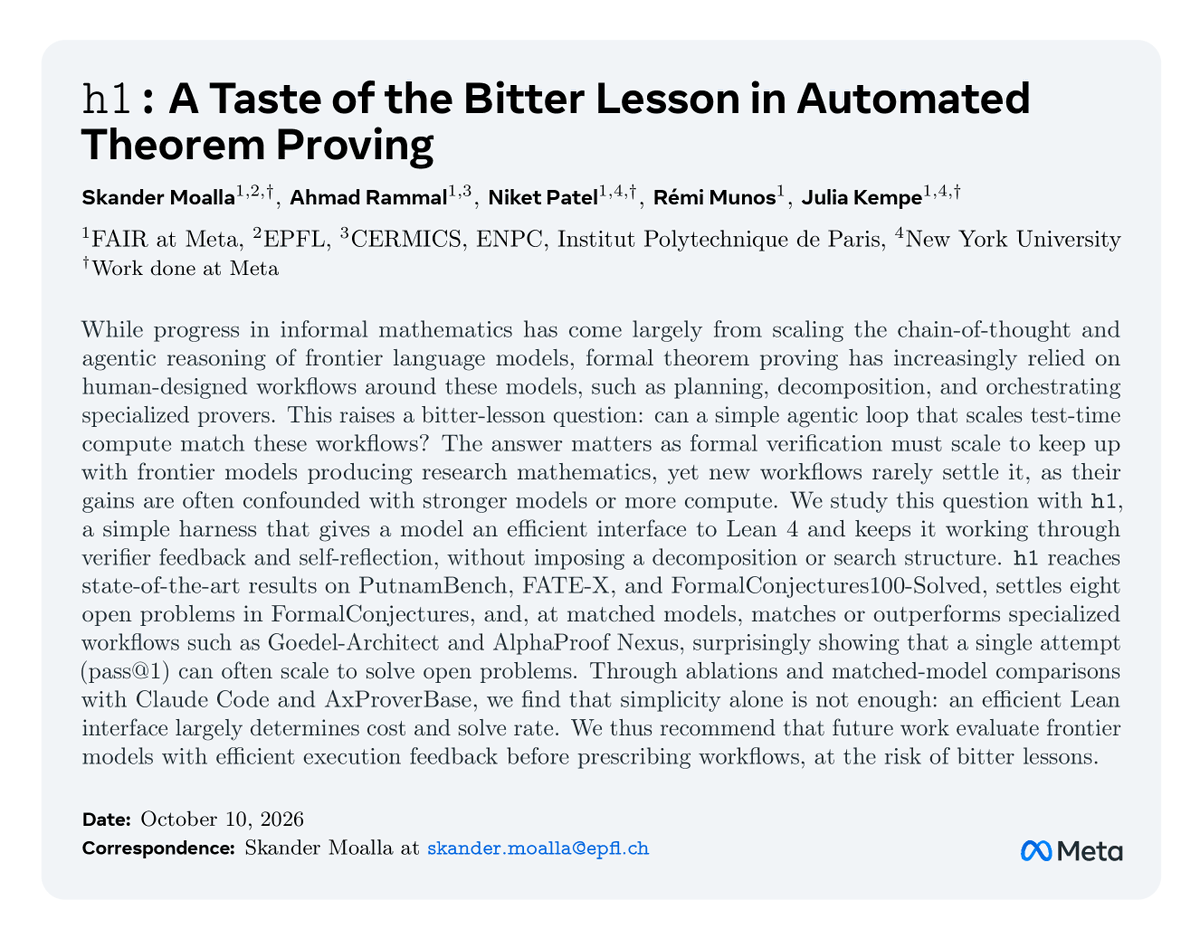
River AI launches system for building custom internal models
Igor Babuschkin·1 hour ago
Talk: Just-in-Time Ontologies and the Limits of Cheap Intelligence
Hrishi Olickel of Southbridge AI recounts a pipeline that stripped minus signs from loan amounts, turning a net $784,000 into $5.3 million of debt, with multiple models agreeing on the wrong result. He argues data transformation needs more than a universal schema or a confident agent.
YouTube·1 hour ago
Microsoft Research's StudentSim simulates students to test AI tutors
StudentSim trains personalized AI student simulators from public, de-identified learner records, one simulator per student, so tutors can be evaluated before real-learner studies. It beats leading baselines across chess, second-language English writing, and math, and is a research system, not a deployed classroom product.
Microsoft Research·1 hour ago
