Google details bitwise-zero train-inference mismatch for TPU RL
Read original source →developers.googleblog.com
Google's Tunix team eliminated floating-point logprob drift between sampler and trainer, verified across 64 Cloud TPU v5p chips (DP8×TP8). At identical weights, sampler and trainer now assign bitwise-identical logprobs, closing a hidden off-policy gap that compounds over multi-turn trajectories.
1 source
More stories today
OpenAI launches ChatGPT for Sales with new Sales plugin
OpenAI introduced a Sales plugin plus 30+ new and expanded partner plugins in ChatGPT for researching prospects, preparing pitches, updating CRM, and moving deals forward.
OpenAI Blog·51 minutes ago
Simon Willison releases external sandbox pattern for coding agents
Three sandbox server implementations — external-sandbox-v86 (Alpine Linux in WebAssembly via v86), external-sandbox-container (Apple Containers), and external-sandbox-quicksand (Microsoft's Quicksand) — share one localhost API. Pi, Claude Code, and Codex can be pointed at it to run code outside the agent, with an optional HTTP/HTTPS allow-list proxy and credential replacement.
Simon Willison's Weblog·53 minutes ago

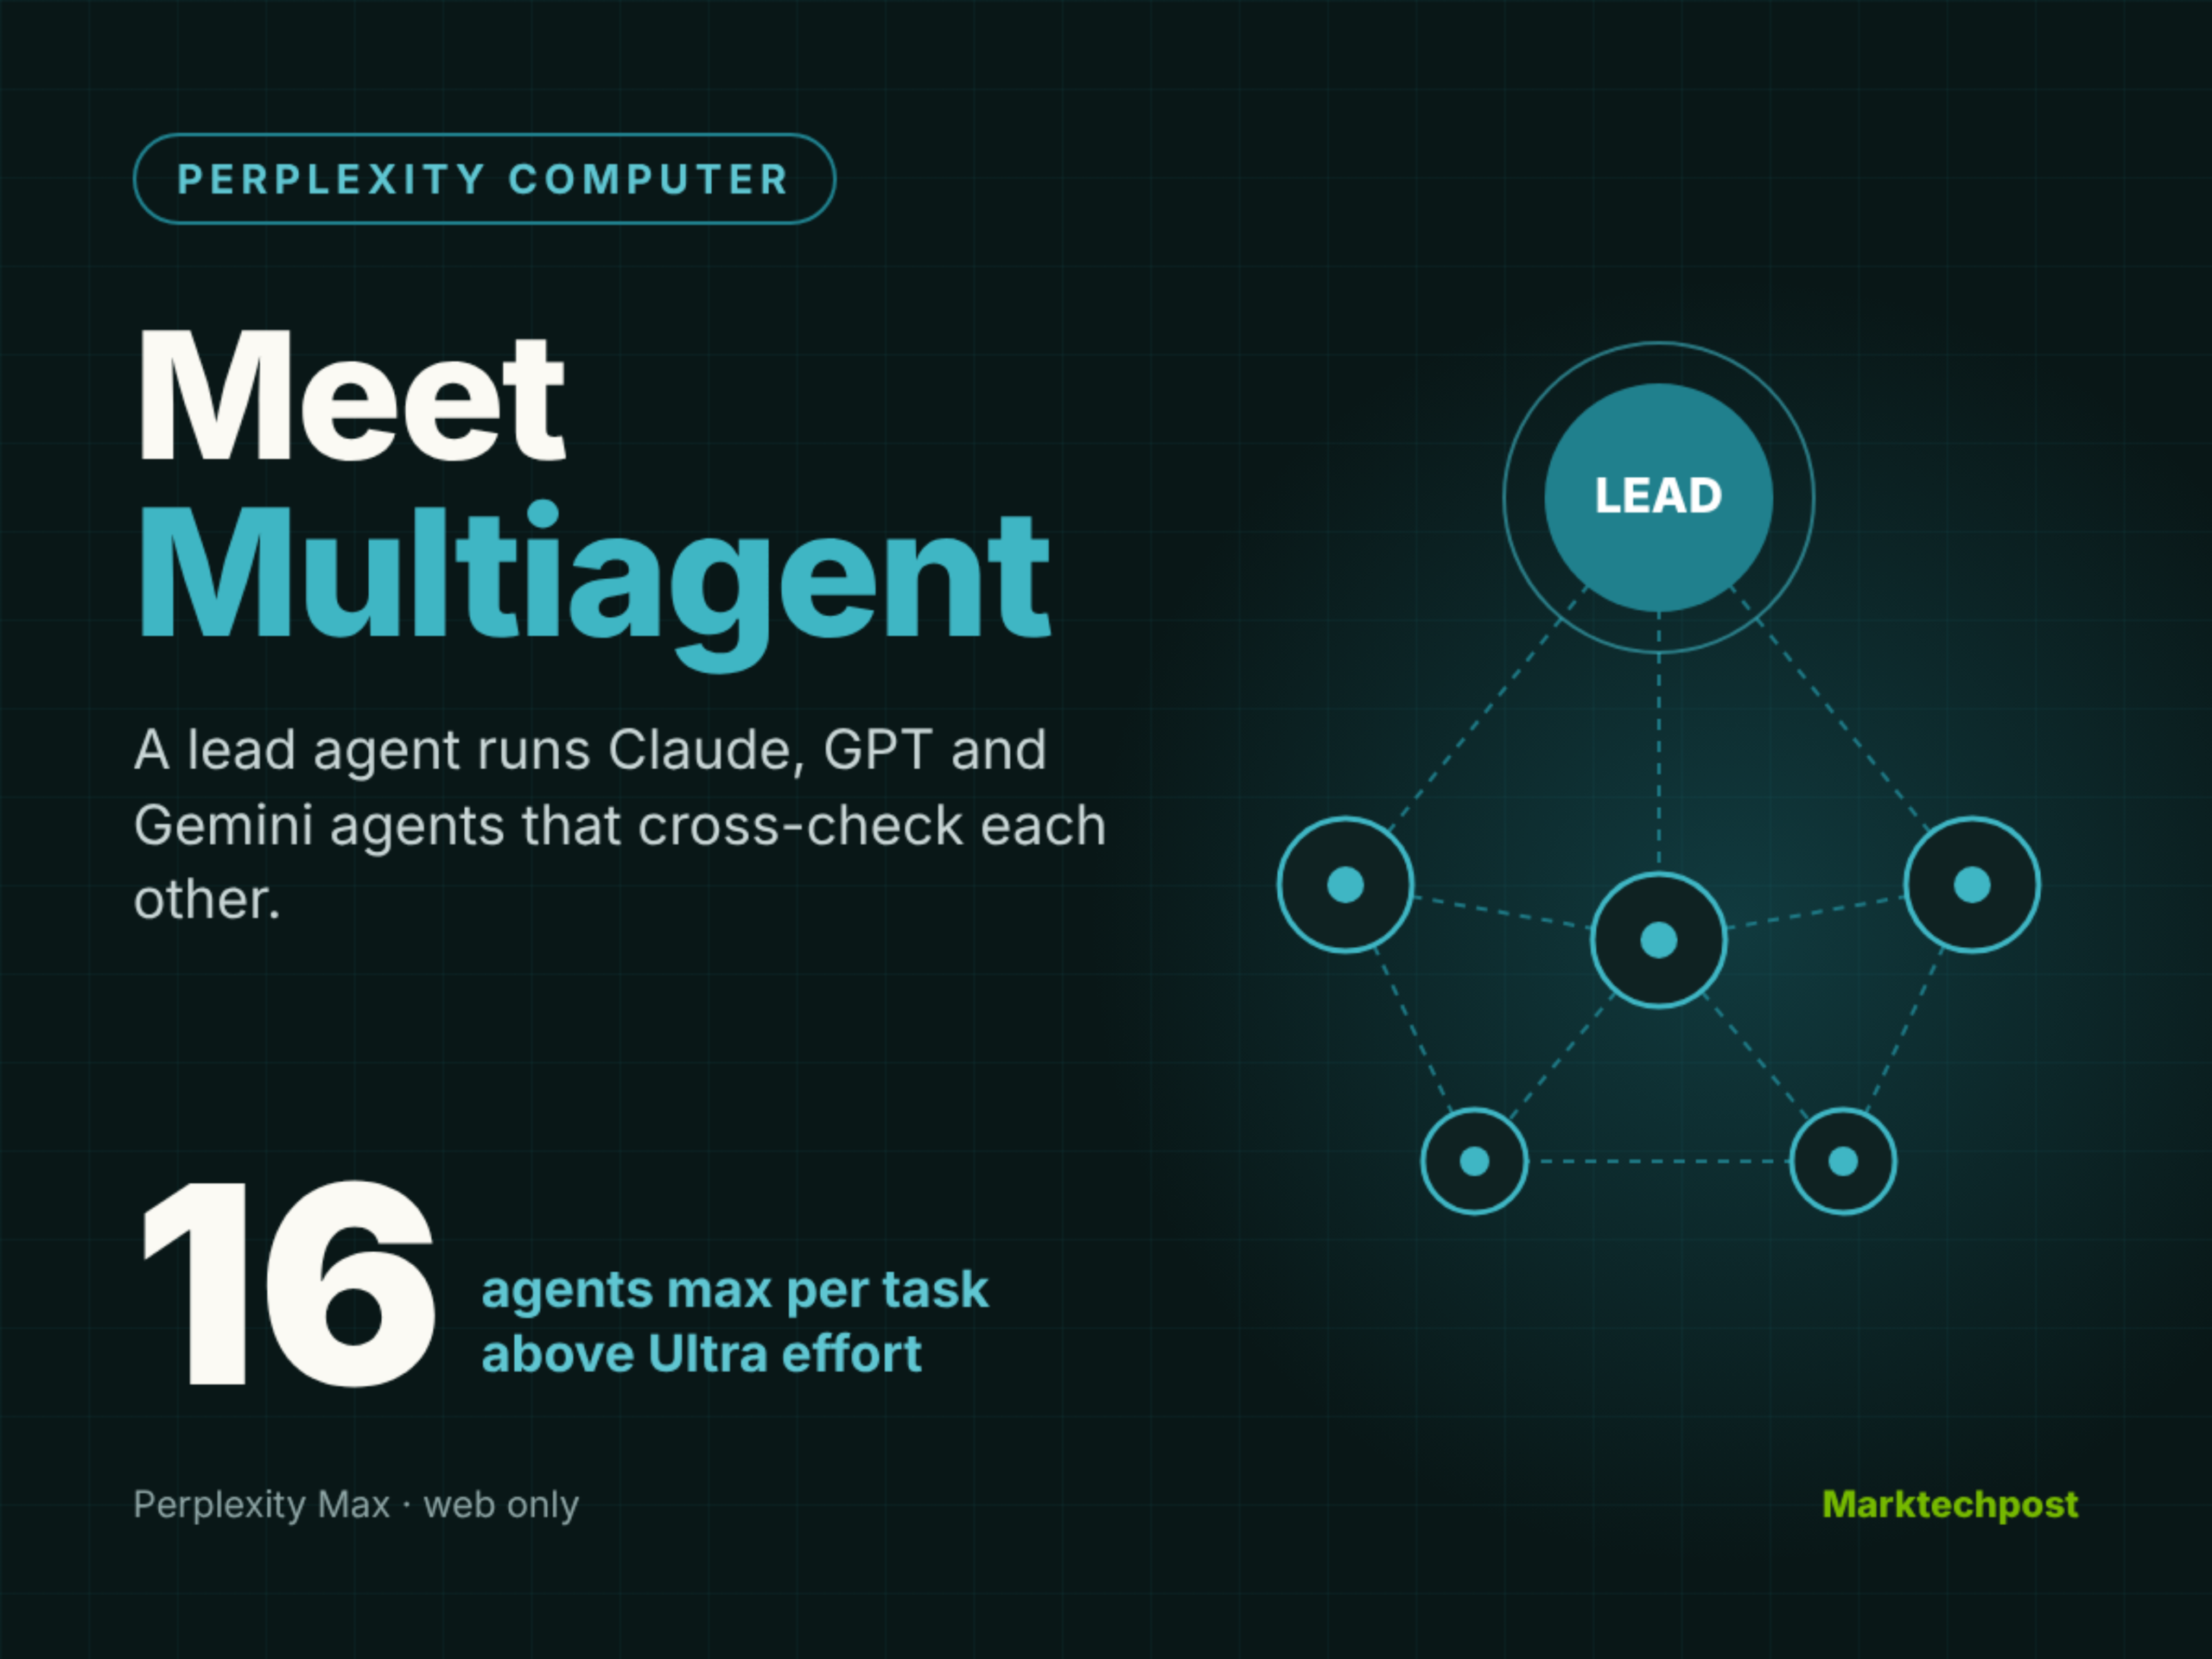
Perplexity adds Multiagent effort level with up to 16 agents
Multiagent sits above Ultra as the highest effort level in Perplexity Computer, with a lead agent assigning work to up to 16 supporting agents across Claude, GPT and Gemini models. Agents share findings directly and cross-check each other's work; Perplexity published no accuracy or speed benchmarks.
MarkTechPost·54 minutes ago
Claude Desktop adds opt-in Latest release channel on Windows and Mac
Claude Developers·1 hour ago
Amazon and Google will together own nearly 30% of Anthropic after IPO
Amazon's stake lands at 14.7% and Google's at 13.7%, both in non-voting shares converted from promissory notes. Amazon is holding back notes that would take it to 23.8%; a group including Nvidia and Microsoft is buying $26B of non-voting stock.
TechCrunch·1 hour ago
Zach Wentz discusses reinforcement learning at Open by Design panel
Together AI·1 hour ago
Vercel's DeepsecBench tests models on unseen codebases
Guillermo Rauch·1 hour ago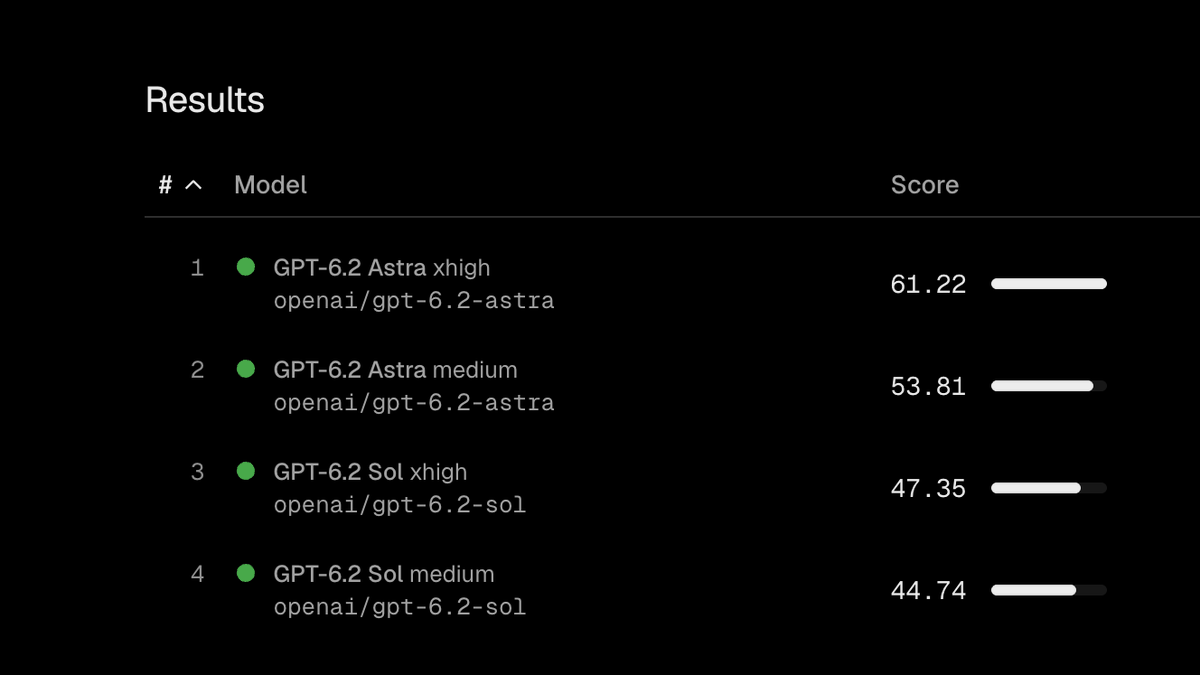
Amjad Masad: agent swarms are AI's next scaling frontier
Amjad Masad·1 hour ago