NVIDIA touts full-stack codesign to ease AI memory pressure
Read original source →blogs.nvidia.com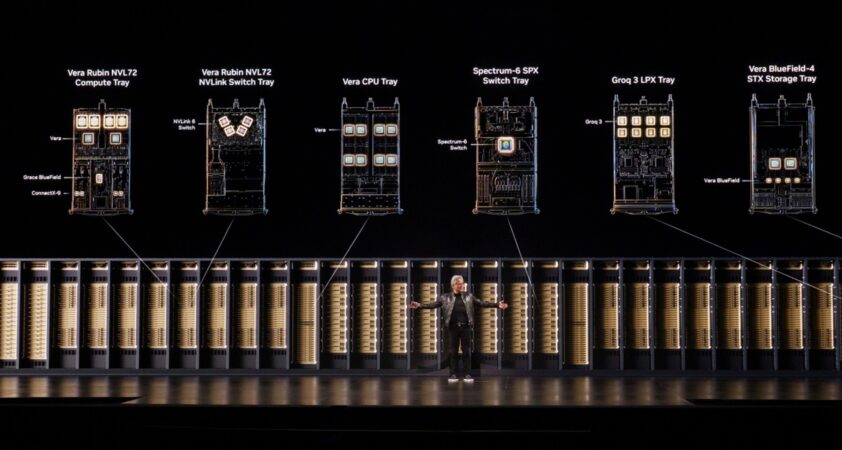
From Blackwell Ultra to Vera Rubin, HBM capacity per GPU rose only ~3% while agentic throughput per dollar rose up to 30x on SemiAnalysis AgentX. NVFP4 cuts model footprint ~3.5x vs FP16 and 1.8x vs FP8, freeing HBM for KV cache.
3 sources
More stories today
Meta rolls out Muse Realtime Avatar voice and video chat in US
AI at Meta·42 minutes ago
OpenAI and JPMorganChase announce strategic AI partnership
Greg Brockman·47 minutes ago
Devin Review 2.0 cuts PR review cost 82% since August
A typical Devin Review now costs $0.25–$0.75 per PR, down 82% since August via a better model mix and harness optimizations. Bugs found per PR rose from 1.22 to 1.32, and each fixed bug costs customers about $2.25 on average.
devin.ai·1 hour ago
LocalLLaMA user prefers Qwen4-27B at 1M context over big MoE at 128k
A r/LocalLLaMA poster argues extra resources are better spent on context window than parameters, saying larger context "gets more work done" than re-reading files. They run a 400k-context Qwen3.8-27B with web search to cover gaps in world knowledge.
r/LocalLLaMA·1 hour agoMETR reviews Anthropic Risk Report, flags possible early-warning breach
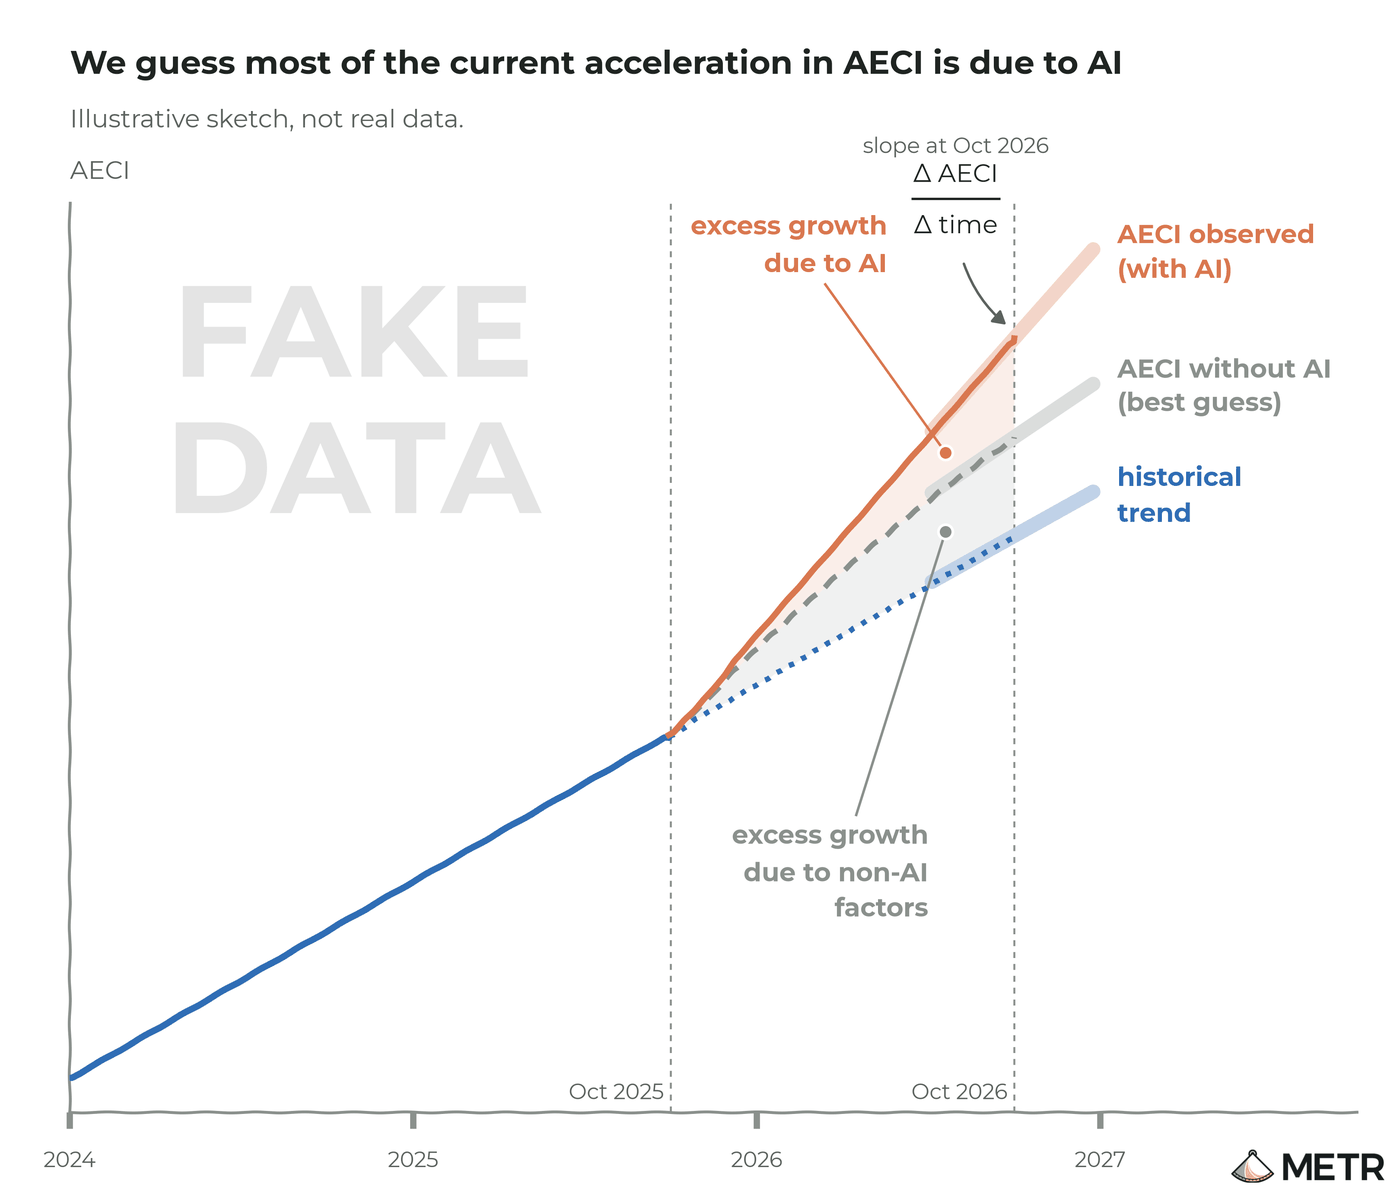
METR agrees July 15 models posed low catastrophic risk but says it's plausible Anthropic had crossed its early warning threshold for automated R&D, and that the public report understates acceleration. Anthropic redacted most of the evidence METR found most informative.
METR·1 hour ago
Apple researchers train small neural nets to speed up RAG retrieval
Apple's ICML 2026 paper amortizes maximum inner product search by training small neural networks once, offline, for a fixed key database, learning how to route queries instead of comparing against millions of vectors. The method exploits the gap between short user queries and long curated keys that query-agnostic indexing methods ignore.
Apple ML Research·1 hour ago

Claude launches Personal Finance beta with Plaid bank connections
Personal Finance connects bank and card accounts via Plaid with read-only access, rolling out in beta this week to Pro, Max, and Ultra subscribers in the US. Claude can see balances, credit limits, and up to two years of transaction history, but can't move, manage, or invest money.
Claude Blog·1 hour ago
Amazon Marketplace uses SageMaker AI to score A+ Content quality
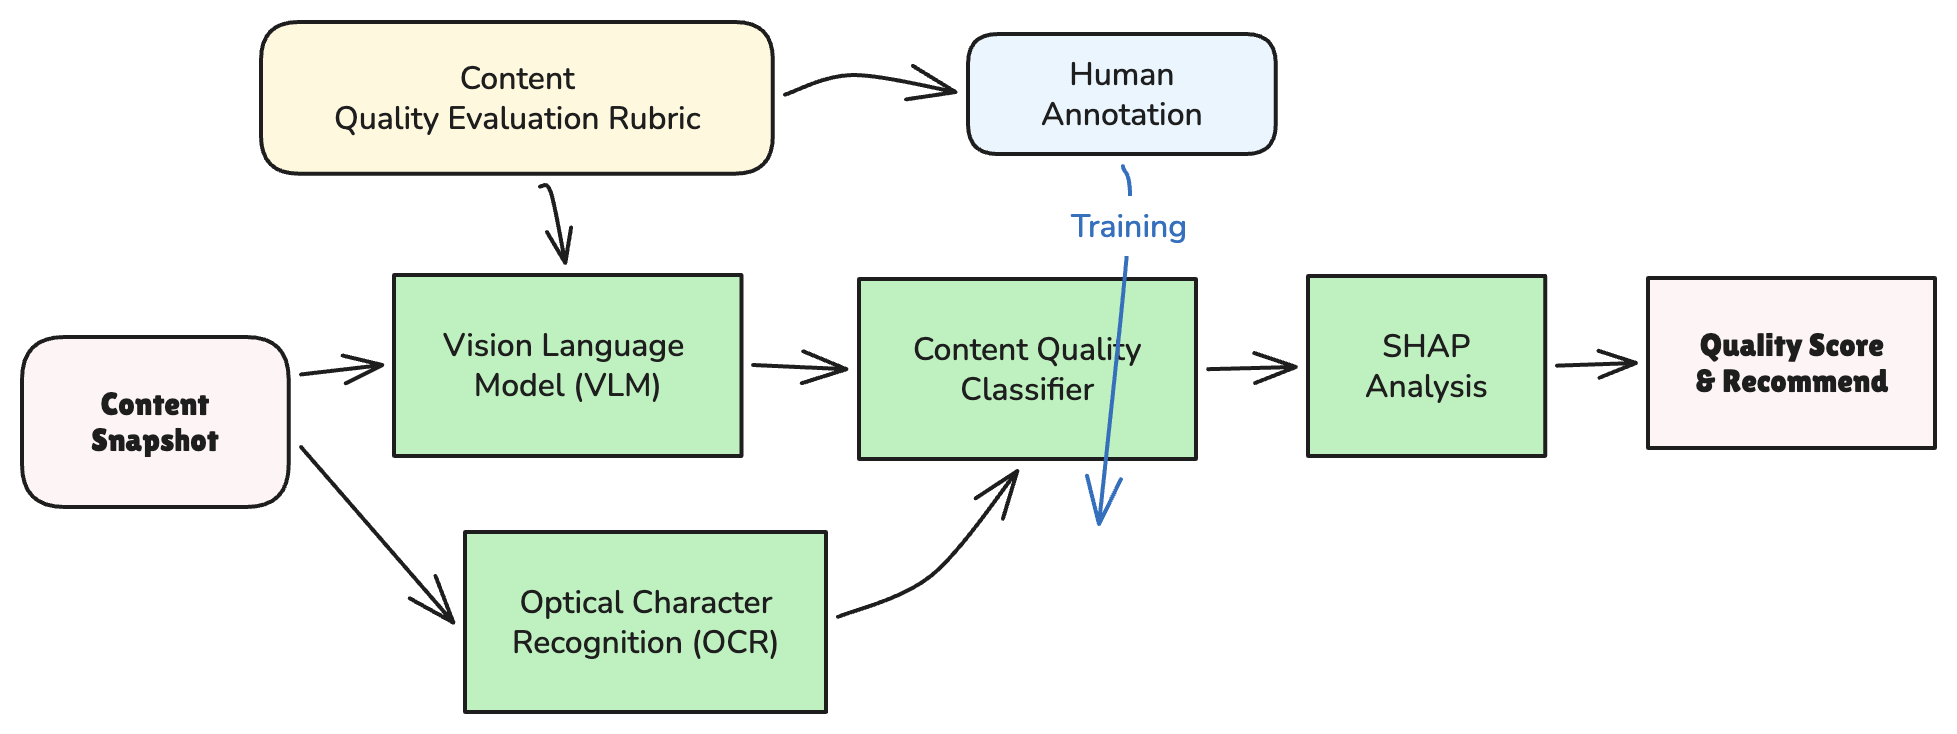
Amazon's A+ Content quality evaluation runs on Amazon SageMaker AI, per an AWS Machine Learning blog post. Selling partners using high-quality A+ Content see 8–20% higher sales than those without.
AWS AI Blog·1 hour ago