Architect launches Liquid Inference, a live auction for LLM inference
Read original source →marktechpost.com
Architect Financial Technologies' Liquid Inference auctions each request across providers quoting the named model; the lowest offer meeting the buyer's rules wins. Buyers set per-job cost caps, time-to-first-token limits, throughput minimums, region and zero-data-retention rules.
1 source
More stories today
1984 Soviet essay 'Why Artificial Intelligence Is Impossible' resurfaces
A 1984 Soviet text by A. V. Brushlinsky, published in the Markov-edited collection 'Cybernetics Today', argues against the possibility of machine thought. The essay is being circulated via an Internet Archive scan.
r/artificial·19 minutes ago
Musk says Grok will use Suno, Claude Opus 5.5 and MidJourney APIs
Musk posted that SpaceX will route Grok tasks to "the best back end model," naming Claude Opus 5.5, MidJourney and Suno. Suno has no public API yet; CPO Jack Brody said a developer API is in the works with a curated partner group.
Music Ally·45 minutes ago

Meta FAIR and Mila train 8B-parameter RoboJEPA on 15,000 hours of robot video
Vai Viswanathan·57 minutes ago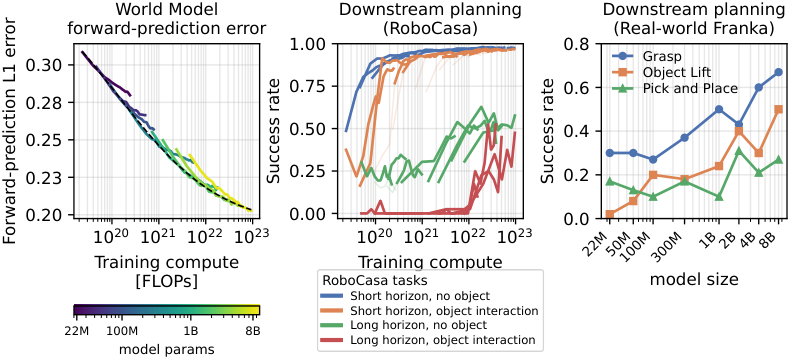
River Recipes open-sources training recipes that beat GPT-6 Astra on text-to-SQL
River AI·58 minutes ago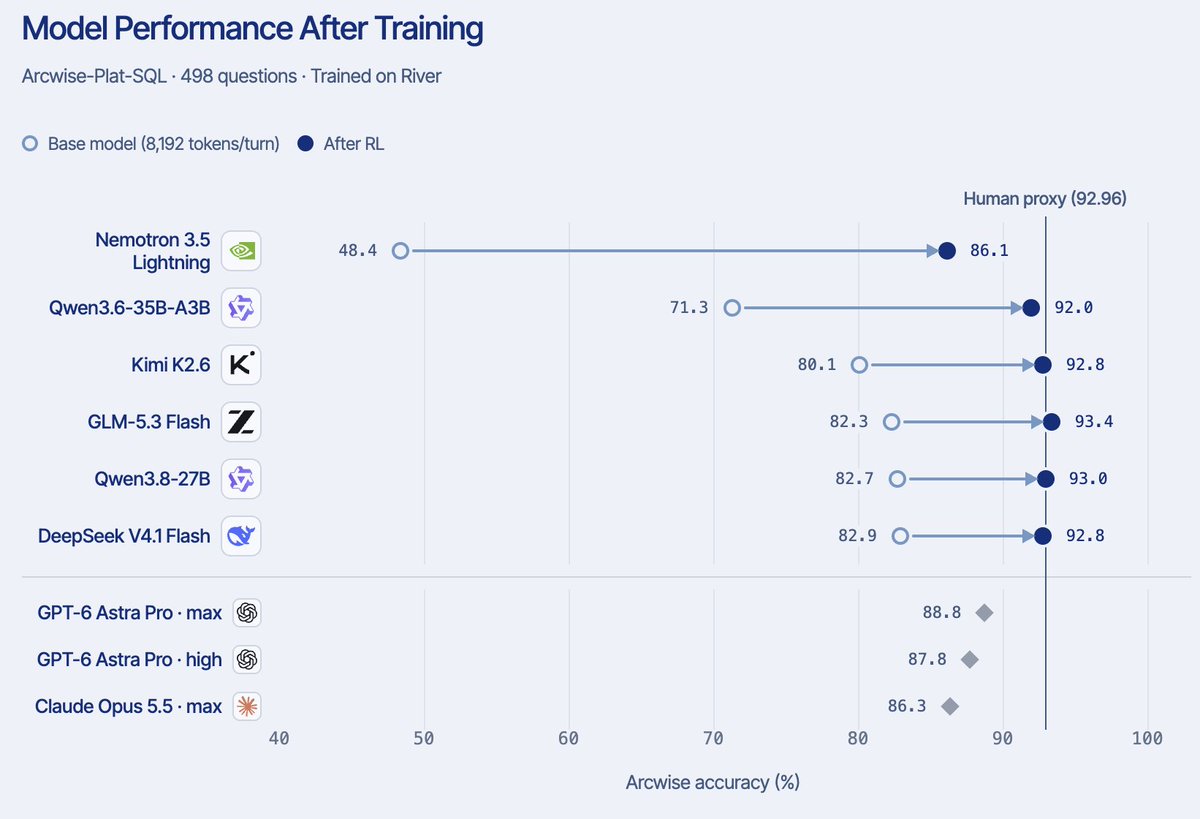
Largest agentic LLM inference dataset released: 206B tokens
Juncheng Yang·58 minutes ago
Creator gauges interest in H3 Long Shot API latent chain workflow
A Reddit user is tweaking a latent chain shot workflow for long-form video generation and asking r/StableDiffusion whether it is worth pursuing. The proposed feature keeps approved shots and advances to the next automatically.
r/StableDiffusion·59 minutes ago
Claude AI agents power viral video game mod mashups
Gamers are using Claude-based AI agents to vibe code "passthrough mods" that run two games at once, producing mashups like Skate inside Call of Duty: Modern Warfare 2 and Minecraft characters fighting Elden Ring bosses. A GitHub guide claims merging Elden Ring and Spider-Man took three to four hours, though first results are often rough.
Decrypt·59 minutes ago
Reddit user benchmarks Qwen3.8-27B fine-tunes against frontier models
A LocalLLaMA user tested Qwen3.8-27B fine-tunes, finding mradermacher/Signal-3.8-27B-Terse-Coder.i1-Q4_K_M best for their use case. They report solve times versus frontier models are 'massive,' especially on low-end hardware.
r/LocalLLaMA·1 hour ago