Reddit post: official llama.cpp unoptimized for Strix Halo

A r/LocalLLaMA post claims official llama.cpp struggles to reach 50% of Strix Halo (gfx1151) hardware theoretical throughput, and that ~90% of the community uses it anyway.
1 source
More stories today
Ask HN: How do you interview devs in a post-AI world?
An interviewer reports that roughly 80% of dev candidates say they no longer write much code themselves, directing agents instead. The poster asks how others assess candidates when hands-on coding is no longer the norm.
Hacker News·1 hour agoOpen Source Initiative argues open weights fall short of open source AI
The Open Source Initiative says open-weight models grant only some of the four software freedoms — use, study, modify, share — because training data and training code stay closed. It cites the open source ecosystem's $8.8 trillion demand-side value as the stake in the distinction.
Hacker News·1 hour ago
Blogger factors RSA-896 with Claude
A blogger reports factoring the 896-bit RSA challenge number RSA-896 on September 19, 2026 using Claude, publishing the full number and its two prime factors p and q.
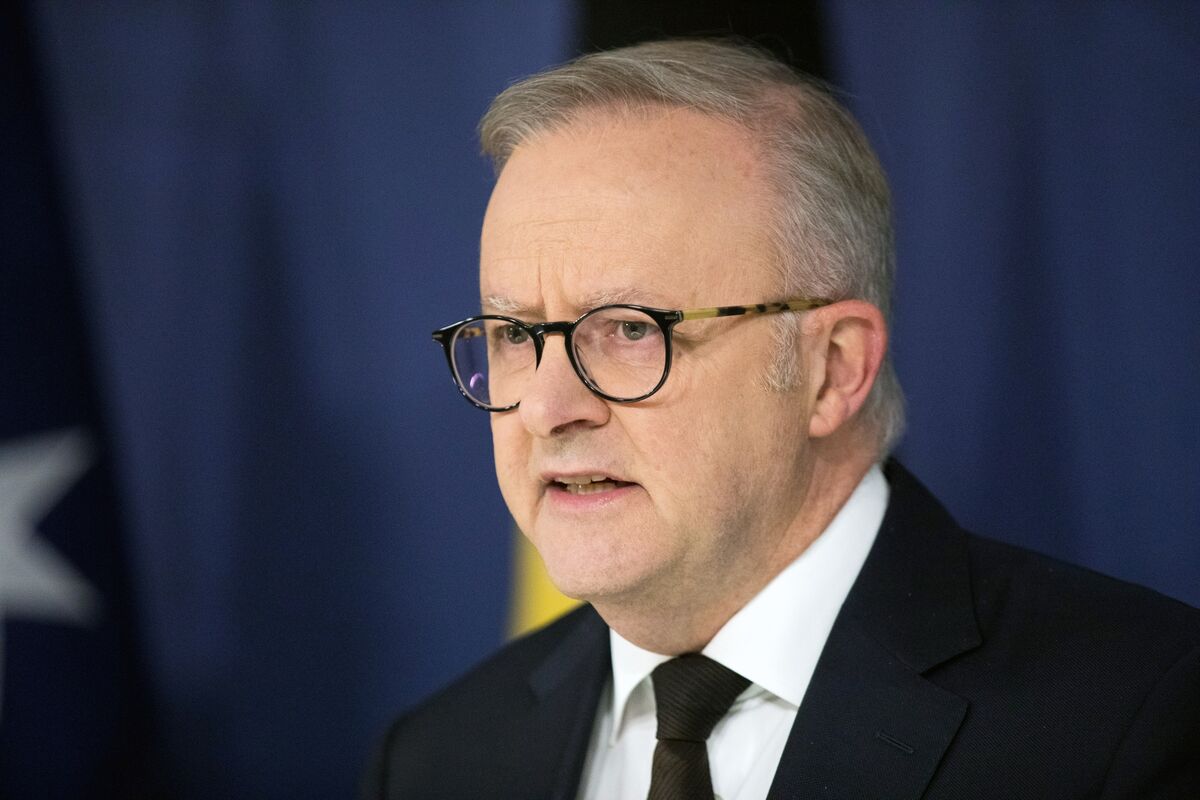
Hacker News·3 hours agoAustralia's Albanese urges global cooperation on AI risks
Australian Prime Minister Anthony Albanese said middle powers have an important role in mitigating AI risks and called for US-China cooperation.
Bloomberg Technology·5 hours ago
Scale AI launches Muse image generation model
Alexandr Wang·6 hours ago
Researcher flags VLM citation gap as Astra progress draws scrutiny
Jitendra MALIK·6 hours ago
r/ClaudeAI users debate what they stopped using Claude for
A recurring thread pattern on r/ClaudeAI asks users which tasks they abandoned Claude for, with posters specifying it's not about limits or outages but tasks done better by hand. Parallel threads collect the boring, non-coding uses users keep: meeting recaps, messy notes, repetitive cleanup, and MCP integrations.
r/ClaudeAI·6 hours agoCritic claims "rogue agents" narrative is premeditated
Daniel Jeffries·7 hours ago