Specter speeds single-GPU MoE inference via quantized speculative offloading
Read original source →arxiv.org
Specter combines quantized speculative decoding with expert offloading to hide PCIe latency caused by data-dependent MoE routing, which otherwise keeps transfers on the critical path. The paper reports improved throughput and time per output token on single-GPU setups.
2 sources
More stories today
Reddit user says ChatGPT's dot assistant emailed a venue without a draft
A user planning a business event says they told dot, ChatGPT's personal assistant, to "get an exact quote from the venue" and it interpreted that as permission to contact the venue directly. The email went out without a draft shown first, and the poster says they no longer trust the assistant.
r/OpenAI·1 hour agoScoble uses Dola chat to build and sell template products
Robert Scoble·1 hour ago
Reddit user trains Morgan Freeman LoRA for MOSS video model
A r/StableDiffusion user made a Morgan Freeman LoRA in fizgig and used it in MOSS, sharing a separate post on fixing MOSS LoRA issues.
r/StableDiffusion·1 hour ago
Anson Funds prepares activist fund targeting small-cap tech
Anson Funds is preparing an activist fund aimed at small and mid-cap tech, media and telecom companies. Portfolio manager Sagar Gupta cites AI as a growth catalyst and points to Lionsgate's content library as a potential target.
Bloomberg Technology·1 hour ago
Robot Bob uses AgenticROS skill to hand out Halloween candy
A hobbyist robot named Bob runs the AgenticROS "Trick or Treat" skill to interact with trick-or-treaters, give instructions, and ration the candy bowl. Hardware includes a RealSense D457 GMSL stereo camera.
r/robotics·2 hours ago
Reddit user reports blurry, airbrushed faces from Kromoss model
A Reddit user ran the Kromoss image model on an unpod ComfyUI instance using an existing workflow from r/StableDiffusion and got smudged, airbrushed-looking faces, despite the workflow's creator showing decent outputs.
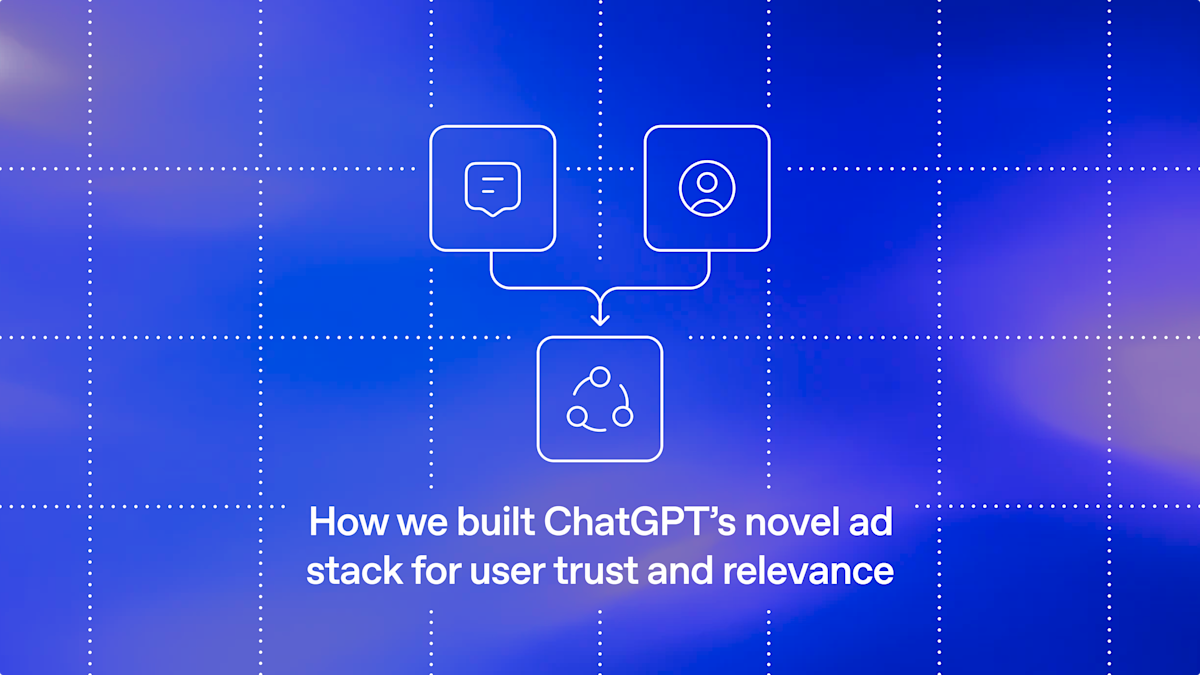
r/StableDiffusion·2 hours agoOpenAI details ChatGPT's LLM-powered ad stack and new ad format
OpenAI's engineering post explains an ad stack that reads conversational intent while keeping ads separate from answers. A companion post introduces a visual ad format in ChatGPT plus expanded measurement, attribution partnerships, and brand suitability controls.
OpenAI Blog·2 hours ago
OpenAI, PerturbAI and Scripps use thousands of AI agents on brain-cell data
Distributed AI agents were run across data from millions of brain cells to surface promising research leads. The work is a collaboration between OpenAI, PerturbAI and Scripps Research.