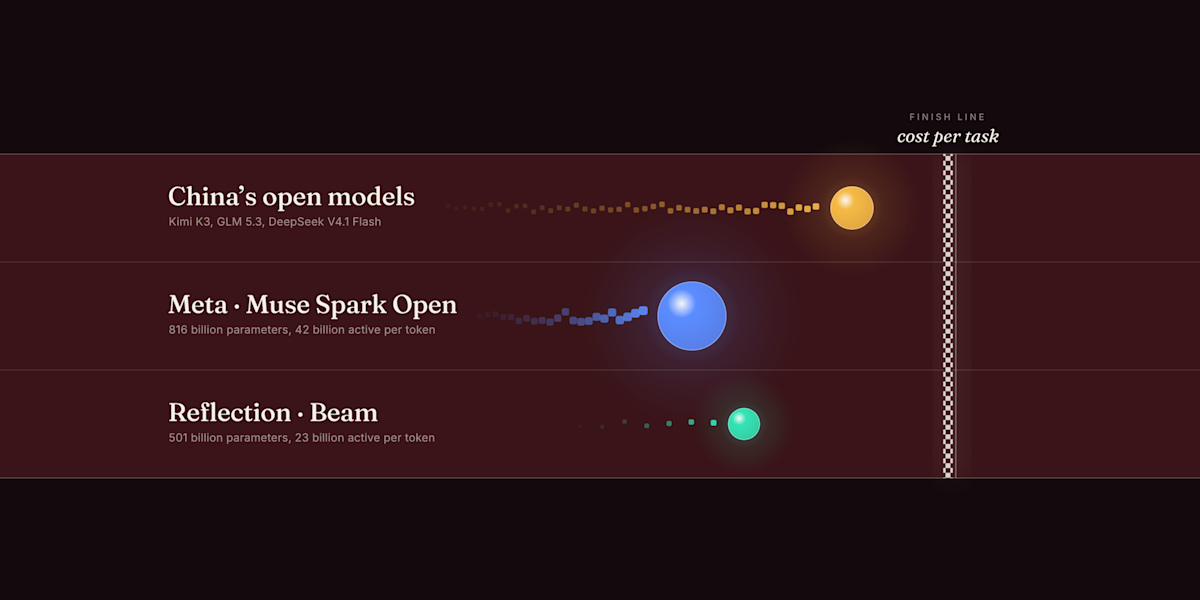
Muse Spark Open is an 816B mixture-of-experts model with 42B active parameters and a 1M-token context window, scoring 39 on the Artificial Analysis Intelligence Index — the #1 US open-weights model. It beats Nemotron 3 Ultra on agentic tasks and scored 22 points above Meta's 30B dense Muse Glimmer.
Meta Superintelligence Labs shipped the Muse Wonder series, its second-generation family, roughly 14 months after the lab was founded. Muse Wonder is available via the Meta Model API and Muse Code; Muse Wonder Full is limited to Muse Code subscribers. Trained at Meta's gigawatt-scale Prometheus data center.
Nemotron 3.5 Super VL is a 120B-parameter mixture-of-experts model activating 12B parameters per token, with up to 1M tokens of context and native MTP speculative decoding. NVIDIA also shipped Nemotron 3.5 Bolt 74B-A9B 24GB for local RTX/DGX Spark agents, with Bolt E4B 4GB due Oct. 23.
Beam is a sparse MoE with 501B total and 23B active parameters, a 1M-token context window, and Apache 2.0 weights released with 40+ ecosystem partners. It scores 30 on the Artificial Analysis Intelligence Index, placing #2 among US open-weight models.
RTX Spark pairs an NVIDIA GB10 system-on-a-chip (Grace CPU + Blackwell GPU) with up to 128GB unified memory and 1 petaflop of FP4 AI compute, letting developers run coding agents locally. Artificial Analysis clocked a local agent workload on Qwen3.8 27B at 18.7 minutes.
Mistral Large 4 is a 1T-parameter natively multimodal model with 49B active parameters, trained on 3,800 NVIDIA Grace Blackwell GPUs in Mistral's European datacenters. The preview API is live on Mistral Studio; weights drop end of this month.